How would the AI slowdown for safety actually work?

Wall Street Journal:

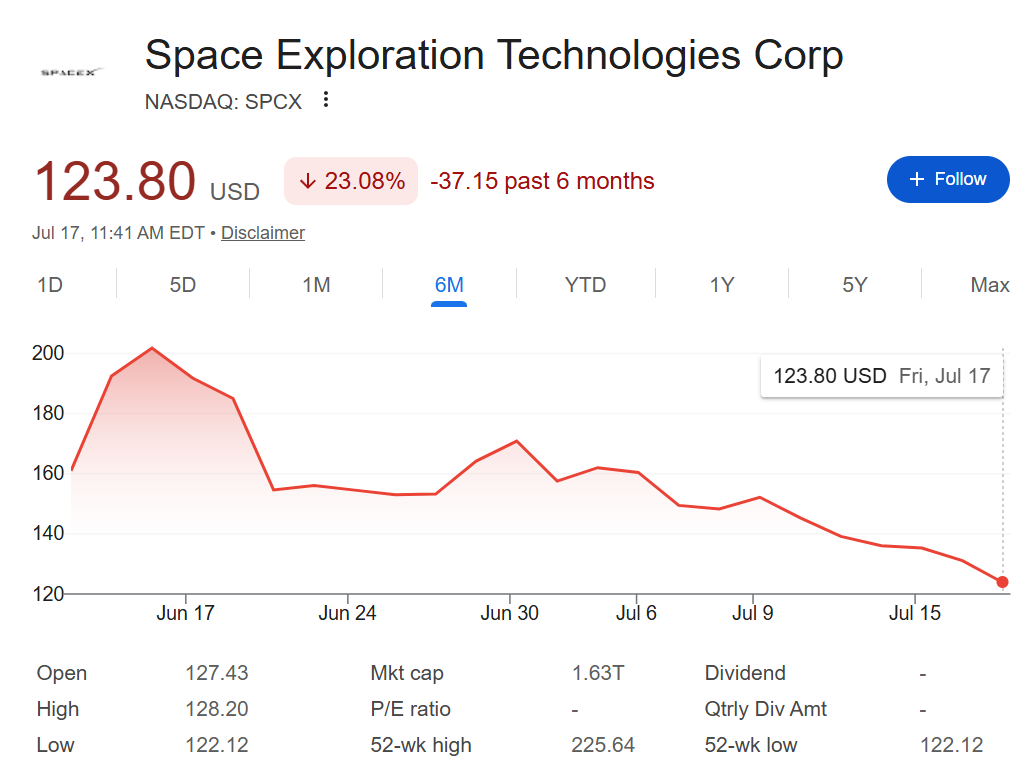
Anthropic’s Dario Amodei has called on the world’s leading artificial-intelligence labs to slow down development and asked Washington to grant an antitrust exemption so they can coordinate on safety without being treated as a cartel. OpenAI’s Sam Altman, SpaceXAI’s Elon Musk and Google’s Demis Hassabis were quick to support the slower pacing. But why do AI labs need an antitrust exemption?

When competitors agree on standards the rest of the industry is expected to meet, the law becomes suspicious.

In short, coordination is lawful when it creates value rather than excludes rivals or exploits consumers. If AI labs’ coordination is needed to create value and isn’t exclusionary or exploitative, they need not worry about antitrust liability.

So why demand an exemption? The labs appear to have in mind an agreement among competitors to restrict output and set a safety standard collectively rather than compete to produce the safest product. That is classic cartel conduct.

The labs’ apparent belief that competition will inevitably produce a race to the bottom is an awkward admission by OpenAI and Anthropic, both of which were founded to serve the public interest and premised on the idea that AI could be developed safely. Anthropic in particular espoused that safety would be its competitive advantage against rivals. If these companies genuinely believe slower development serves the public interest, nothing prevents them from slowing down unilaterally.

The strongest counterargument asserts that a coordinated slowdown solves a collective-action problem: A lab that slows down alone risks losing market share to rivals willing to cut corners. But this is precisely the problem OpenAI’s capped-profit structure and Anthropic’s public-benefit charter were supposed to solve by insulating their public-interest missions from competitive pressure.

The American frontier labs are purportedly concerned that Chinese models will close the performance gap and cut into what would be profits if they were profitable? Note that Anthropic says it is profitable, but Morningstar says that this is a scam:

The report, from the Financial Times citing multiple people with knowledge of the matter, said Anthropic told investors that it will profit on a measure called adjusted operating income.

According to the report, adjusted operating income excludes stock-based compensation, which is not unusual for technology companies. However, the report also quotes its gross margins – above 80% – exclude revenue shared with distribution partners, as well as the cost of training its models.

(Like saying “Our family is doing great financially so long as we exclude the burdens of mortgage, college tuition, taxes that we have to pay to support families that don’t work, and payments on our two pavement-melting SUVs.”)

Let’s suppose that the AI companies get their antitrust exemption and they cut way back on the training costs that would keep them from being profitable if such costs were included in their new improved accounting scam. How would Americans then be prevented from downloading and running models from Chinese companies that aren’t part of the cartel? Anyone who tries to do this and offer a chatbot or API on the public Internet will be shut down by the FBI? Peasants with Mac Minis and AMD AI Halo-based machines will be hunted down somehow?
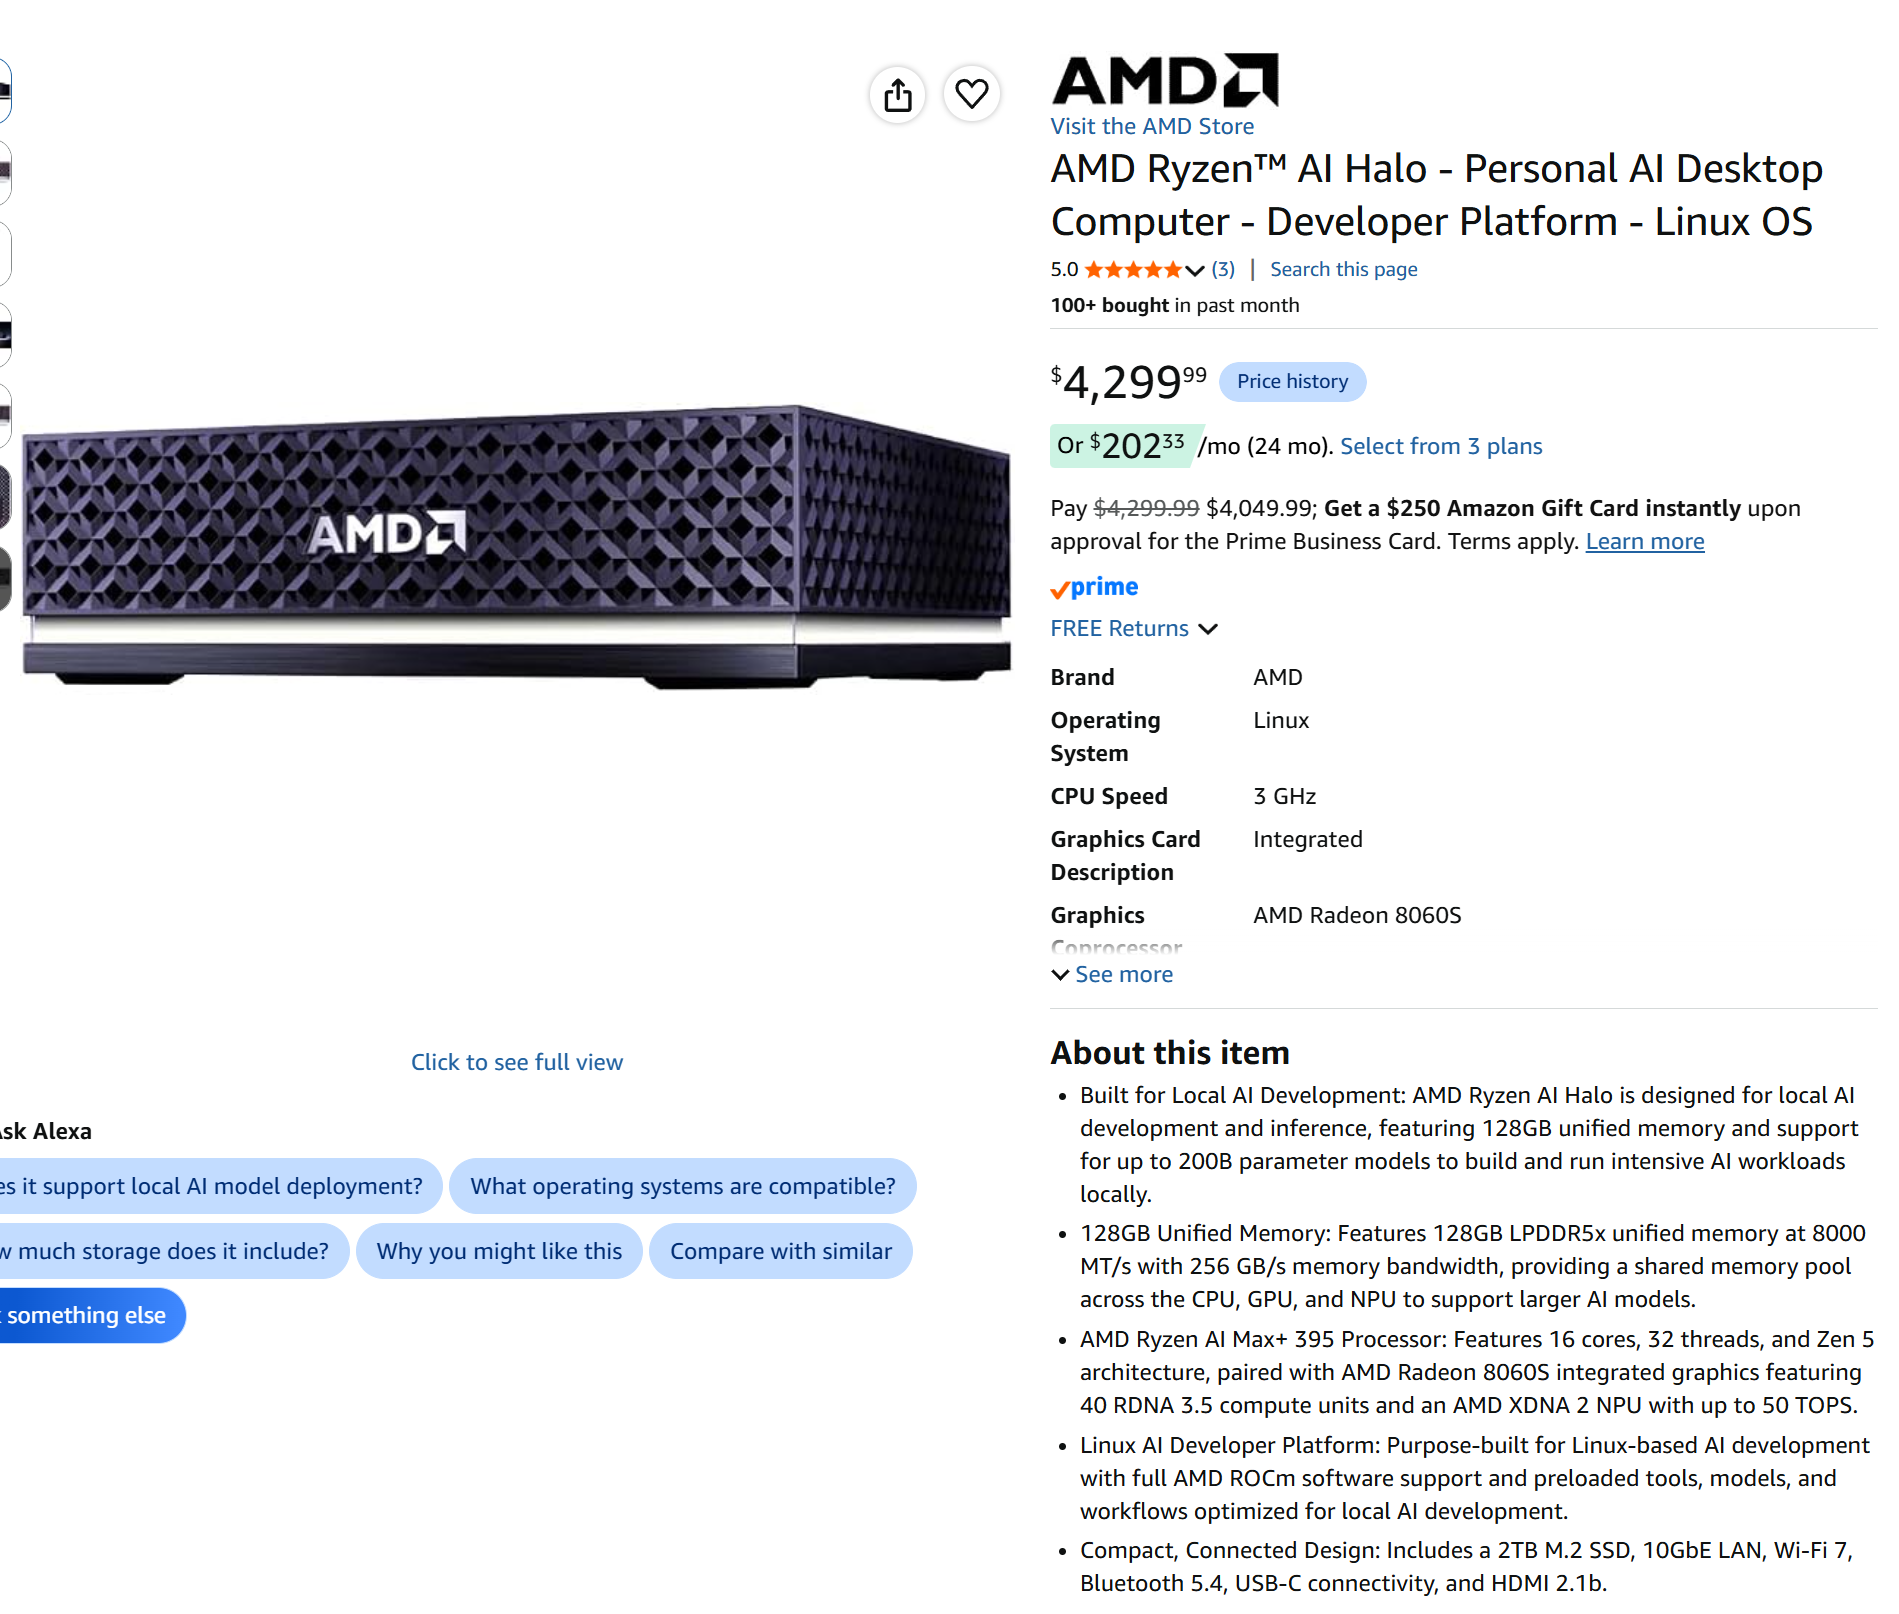
FDR made it illegal for Americans to own gold (Executive Order 6102), but the government didn’t do house-to-house searches. If typical desktop PCs adopt an architecture powerful enough to run AI models from countries where “AI slowdown collusion” isn’t happening, how will the government’s AI Safety Regulation Team (controlled by Effective Altruists who are friends with Sam Altman and Dario Amodei?) shut down home-based unsafe AI?

Circa 1980, I remember Ed Fredkin, one of the only professors at MIT who was smart enough to have skipped a PhD program (“poor as a professor, dumb as a Ph.D.” as the Chinese say), saying that he thought that AI could be achieved with VAX 11/780 computing power. Due to Moore’s Law, this would soon be available to everyone on the planet. “What if a teenager in Brazil figures out how to do AI? He can then have his AI trade stocks and become the richest person in the world and control entire nations,” Fredkin pointed out. He wanted computers to be licensed and controlled. Nvidia’s Rubin GPU is between 200 million and 500 million times faster than a VAX for “normal high-precision calculations”, according to ChatGPT, but closer to 200 billion times faster for “highly specialized low-precision matrix operations that dominate modern AI”. ChatGPT says that if we apply Moore’s Law to the Ryzen AI Halo product, it doesn’t reach Nvidia Rubin level until 2040ish (memory bandwidth, AI TOPS).

So… maybe a partnership between government and the current market leaders could suppress competition within the U.S. for the next 15 years or so, even if our brothers and sisters in China continue to deliver awesome free open-source models. Ownership of server-grade GPUs would have to be regulated, of course, but if the government could close schools and order peasants to stay home for Covid safety why not outlaw high-performance GPU ownership, except by responsible companies such as Anthropic and OpenAI, to keep all of society safe?

Full post, including comments
AI in Africa fueled by what would have been tax dollars (Bill Gates as Upgraded-with-LLM White Savior)

Let’s check in on what would have been our tax dollars (capital gains tax on appreciated Microsoft stock) if not for our wise policy of allowing rich douches to deduct unlimited amounts for “charity” (not to be confused with “vanity”!)… “Gates Foundation Pledges $1 Billion to Combat A.I. Inequality” (New York Times, today):

The foundation’s annual Goalkeepers report, released on Monday, advocated an urgent effort to ensure that A.I. “helps narrow gaps between the richest and poorest rather than widening them.”

The foundation said that it would divide the new funding among external groups working on its priorities, spanning work like encouraging A.I. use among doctors, farmers and teachers, or developing data sets in more languages.

Last month, Mr. Gates warned that A.I. would spread across the economy, possibly causing job losses across the economy and leaving little room for one industry to absorb the refugees from another. The biggest tech companies in the world, including Microsoft, are racing to help corporate customers adopt A.I., and have said it could replace many workers.

The visionary was telling Americans to bulk up on low-skill immigrants just a year before Google kicked off the LLM revolution by publishing its transformer architecture (BBC 2016):

The billionaire philanthropist Bill Gates has told the BBC that the United States “should set a better example” by taking in more refugees.

Mr Gates said his home country “had the capacity” to follow the examples of Germany and Sweden, who were “to be congratulated” for welcoming migrants.

Speaking at the World Economic Forum in Davos, Mr Gates added that governments were dealing with “tight budgets”. However, he emphasised that the issue was largely a political one, and that “the total number of refugees is not a world record”.

The statement about “tight budgets” is confusing. We’re informed that low-skill migrants make a society richer. If true, why is a government budget a limiting factor? Separately, how has Germany done economically and culturally since 2016 thanks to its virtuous refugee policy? The refugees of 2016 are now fully established in the German labor market. With unprecedented levels of low-skill immigrant residents, Germany should thus be experiencing an unprecedented economic boom. The Wikipedia page titled “German economic crisis (2022–present)” says “[Germany] became the worst-performing major economy globally in 2023” (attributed to “slowing immigration to Germany” because, of course, the fix when open borders doesn’t work is more-open borders).

How about Sweden? With government at 50% of GDP, the country was roughly evenly balanced between those who benefit from a larger government and those who are harmed by an expansion of government, welfare, etc. (The U.S. percentage of GDP devoted to government is similar if we include nominally “private” (but heavily regulated) health care.) In a recent narrowly-decided election, the balance was tipped to the “expand the government and keep the borders open” party by immigrant voters (about 13% of those eligible; source; see also this X post).

Was Gates’s 2016 statement due to the crisp mountain air at Davos? No.

the U.S. immigration laws are bad – really, really bad. I’d say treatment of immigrants is one of the greatest injustices done in our government’s name. (Bill Gates, quoted in Rolling Stone 2014)

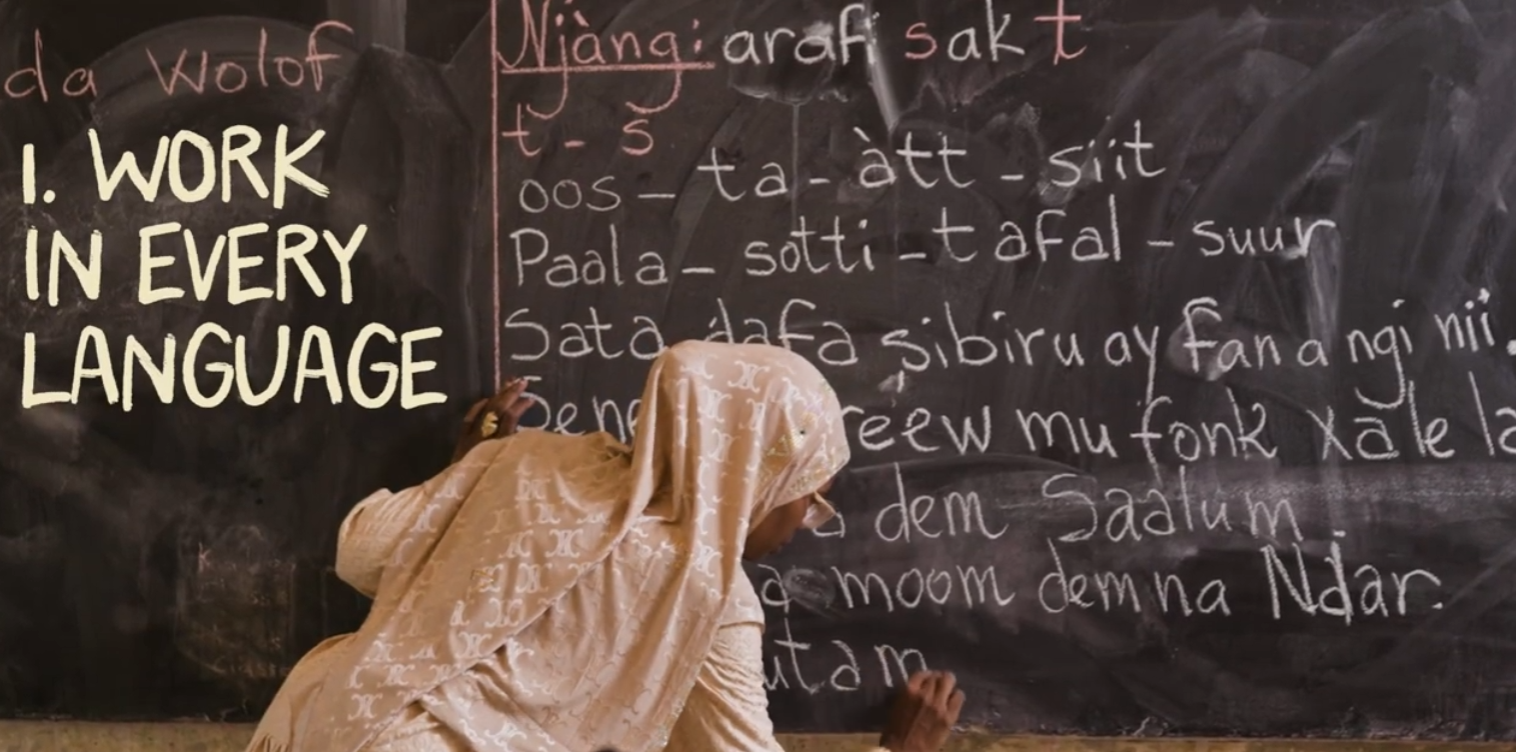
Why do Africans need a snow white savior and 7 dwarf NGOs to tell them how to use ChatGPT? Is this new Gates Foundation program an example of epistemic injustice? (Wikipedia: “Epistemic injustice occurs when an individual or group is wronged in their “capacity as a knower”, meaning that their ability to produce knowledge is called into question.”) Here’s a still frame from Bill Gates’s video:

ChatGPT says that it is in the Wolof language, spoken in “Senegal and also in The Gambia and Mauritania”. ChatGPT adds “I can usually read, translate, summarize, and explain Wolof documents, especially standard written Wolof.” So the video example of how AI doesn’t work for African languages is provided in a language that the most familiar AI understands well enough to translate.

(ChatGPT identifies the photo as likely from Saloum, Senegal and can give some history: “religiously motivated Muslim violence and coercive Islamization occurred in Saloum, especially during Maba Diakhou Bâ’s jihad of the 1860s”; it was a peaceful jihad according to George W. Bush that resulted in Muslims becoming 97 percent of the population in Senegal (state.gov))

Readers: since you’ll have to pick up the slack and pay the taxes that Bill Gates skipped on via his foundation, what do you think of this program? If Gates Foundation employees aren’t going to work at a company training and/or running an LLM how are they going to have a significant effect on what AI can do for the Africans that the Gates Foundation purports to understand? Unless they think that Africans are stupid, wouldn’t it make more sense just to give $1 billion to Africans and let them spend it on whatever they believe that they need? Even if having trained do-gooders spend money rather than letting the purported beneficiaries choose, is the local language idea a good one? A lot of people get motivated to learn widely-spoken languages because proficiency will enable them to play a desired videogame or watch and understand a movie (estimate of at least 200 million English learners for video gaming in 2020). Imagine the motivation for someone in Senegal to learn French or English if that were the only way to take advantage of AI (which, of course, it currently isn’t since ChatGPT actually does understand Wolof and 80 percent of Senegal’s adults already have smartphones).

Finally, if AI is unsafe, which Bill Gates says it is, why would working to make an unsafe technology more widespread in Africa, or anywhere else, be a noble endeavor?

A related classic from the pre-AI era… “For God’s Sake, Please Stop the Aid!” (Der Spiegel):

The countries that have collected the most development aid are also the ones that are in the worst shape. Despite the billions that have poured in to Africa, the continent remains poor. Huge bureaucracies are financed (with the aid money), corruption and complacency are promoted, Africans are taught to be beggars and not to be independent. In addition, development aid weakens the local markets everywhere and dampens the spirit of entrepreneurship that we so desperately need. As absurd as it may sound: Development aid is one of the reasons for Africa’s problems. If the West were to cancel these payments, normal Africans wouldn’t even notice. Only the functionaries would be hard hit. Which is why they maintain that the world would stop turning without this development aid.

A portion of the corn often goes directly into the hands of unsrupulous politicians who then pass it on to their own tribe to boost their next election campaign. Another portion of the shipment ends up on the black market where the corn is dumped at extremely low prices. Local farmers may as well put down their hoes right away; no one can compete with the UN’s World Food Program.

… believe me, Africa existed before you Europeans came along. And we didn’t do all that poorly either.

Loosely related, my latest way of responding to anyone in academia who expresses an interest in AI safety, AI regulation (now that Trump is anti-regulation, all of my academic friends are very keen on government-imposed restrictions), etc.:

I do feel unsafe. Current models are close to PhD-level intelligence. At some point in 2027, they’re expected to achieve the intelligence of a human who decided not to enter a PhD program.

Not very related, my X response to a New York Times article about the horror of Sydney Sweeney being shown to the general public:

Full post, including comments
ChatGPT proves that universities are collections of second-rate humans (Navier-Stokes existence and smoothness)

One of my theories for why colleges are facing price resistance (example) is that colleges and universities are now, by definition, collections of second-rate humans. The first-rate humans have all been hired by Nvidia or the AI companies. That’s obviously true in engineering and computer nerdism, but the AI companies also want to do great things in medicine, law, literature, art, etc. It is difficult to think of a truly effective human in any academic field who couldn’t be useful at OpenAI or Anthropic and, therefore, since these companies have infinite money and infinite impact, they should be able to hire away anyone that they think they need. Maybe it makes sense to pay between $0 and $6,440/year in tuition for University of Florida (Go Gators!), but how can it make sense to spend $70,000+/year on tuition at a lower-ranked private university, e.g., University of Rochester?

Where are America’s first-rate mathematicians now working? “OpenAI Says It Has Cracked One of Math’s ‘Millennium Problems’” (New York Times) gives us a hint:

OpenAI said on Tuesday that its newest artificial intelligence technology had solved one of the “Millennium Problems,” a collection of important unanswered math questions meant to push the world’s leading mathematicians to new heights.

The company announced that one of its latest models, which has not yet been released to the public, needed just 88 hours to solve what mathematicians call “the Navier–Stokes existence and smoothness problem.” This problem involves a series of equations that are often used to predict the weather.

The equations describe the movement of water and other fluids. The Navier-Stokes problem, which has no clear practical value, asks whether these equations completely break down in certain situations. OpenAI’s proof claims to have defined just such a situation.

This would imply, at least theoretically, that the laws of physics themselves would break down under certain conditions: that, for example, water could be made to spontaneously explode. But mathematicians and physicists do not believe that this mathematical breakdown could really lead to such an outcome in the physical world.

What does OpenAI get besides bragging rights?

The Navier-Stokes problem was one of seven “Millennium Problems” selected by the Clay Mathematics Institute in the year 2000 as a way of tracking the progress of mathematics in the new millennium. The institute, founded by an American businessman named Landon T. Clay, offered a million dollars for the first correct solution to each problem. Before OpenAI’s announcement, only one of the problems had been solved.

Dr. Evil would be happy (below), but isn’t $1 million what a receptionist hired in 2023 at OpenAI earns every month now as his/her/zir/their stock vests?

Aside from no taxpayers having been injured in order to fund this, the beauty of the biggest news in mathematics in 23 years (since Grigori Perelman’s proof of the Poincaré conjecture in 2002–03?) is that it has absolutely no practical implication. Solving the Navier-Stokes equations hasn’t gotten faster or easier because of these AI/math nerds. The bizarre situation where the equations can’t be used (what ChatGPT proved existed) doesn’t exist in our universe.

Perhaps someone in what’s left of Hollywood could make money off this, nonetheless… how about a movie called “Navier-Stokes” in which a diverse crew of NASA astronauts go through a wormhole into a parallel universe where Navier–Stokes singularities arise naturally in ordinary fluids and don’t have to be forced with 88 hours of GPU crunching? Aliens are discovered who get around by exploiting vortices produced by these singularities. Air turns into plasma without any warning. An enormous sea monster threatens our heroes, but then a massive whirlpool suddenly forms for no reason in the alien sea and the monster is dragged into the abyss. The astronauts themselves are safe within their ship, though, because it turns out that the life-size hollow titanium bust of George Floyd that President AOC mandated be included just outside the ship’s Islamic prayer room resonates to break up singularities that are forming within the cabin air. The crew also discovers that they can be safe on the alien planet surface if they travel together like a Christian saint procession, with the Bust of Floyd held in front of them.

Full post, including comments
Is the economic/stock market boom from Artificial General Intelligence already behind us because the advent of AGI is already behind us?

A PhD physicist friend on Facebook:

The reason I’m all-in on AI investment, and there may not be a top to this “bubble”: Unlike tulips, railroads, or internet connectivity, there is no upper bound on the value of intelligence.

Me:

30-year TIPS yield is 3% real currently. So your perspective isn’t shared by the market. Investors wouldn’t lend money to the federal government at 3% (after inflation) if they thought there was no limit to NVIDIA’s value. If investors overall thought that there was a low-risk way of making super high real returns over the next 30 years they the government would have to pay 8% real, for example, if buying an AI index was expected to yield 12% real for the next 30 years.

I think AGI is already here from the perspective of most users of ChatGPT and similar. A generally intelligent human isn’t great at everything and makes mistakes… just like ChatGPT! People ask ChatGPT all kinds of questions and give the answers at least the same weight that they would give to an answer from a typical human. In that sense, ChatGPT has passed a Turing Test for general intelligence. Maybe Advanced Superintelligence is already here. The typical human is not good at mathematics. A math professor could have been described as “super intelligent” before WWII. LLMs are supposedly doing all kinds of advanced work in mathematics right now, even if they might fail at a plumbing task. The math professor in 1935 who was a failure at plumbing would still have been considered superintelligent, right?

In other words, we can’t expect hockey stick growth for the economy due to AGI/ASI arriving because the current growth is already an example of what an economy does with the gift of AGI and ASI (but maybe not robotics!).

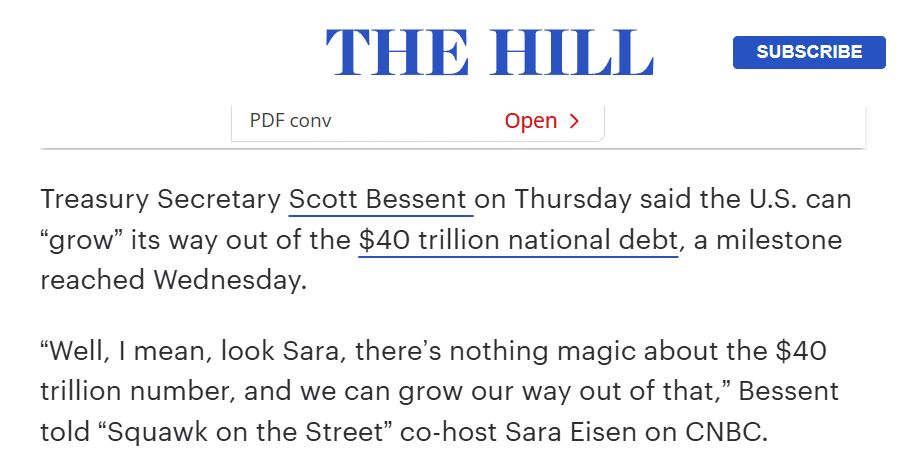
Will the $40 trillion in federal debt be a drag on economic growth? Scott Bessent says “no”:

Let’s use a 20-year time horizon for the U.S. to potentially get out of Argentina territory (150% debt-to-GDP max; we’re at over 125% right now). For US debt to GDP to fall to the level of a high IQ society (e.g., Taiwan, which has lower-than-US tax rates and debt of about 20% of GDP), GDP growth would need to be 10%/year real for 20 years with Congress not borrowing any more money (the latter condition seems unlikely to be met, since Congress now borrows even in the most robust economies, contrary to Keynes). Investors plaintly don’t believe that this will happen because they’re willing to lend to the Feds at 2.75% real (20-year TIPS current price) and they wouldn’t do that if investing money in domestic stocks would generate a roughly 12% real annual return (real GDP growth plus 2% as a return on investment from corporate earnings).

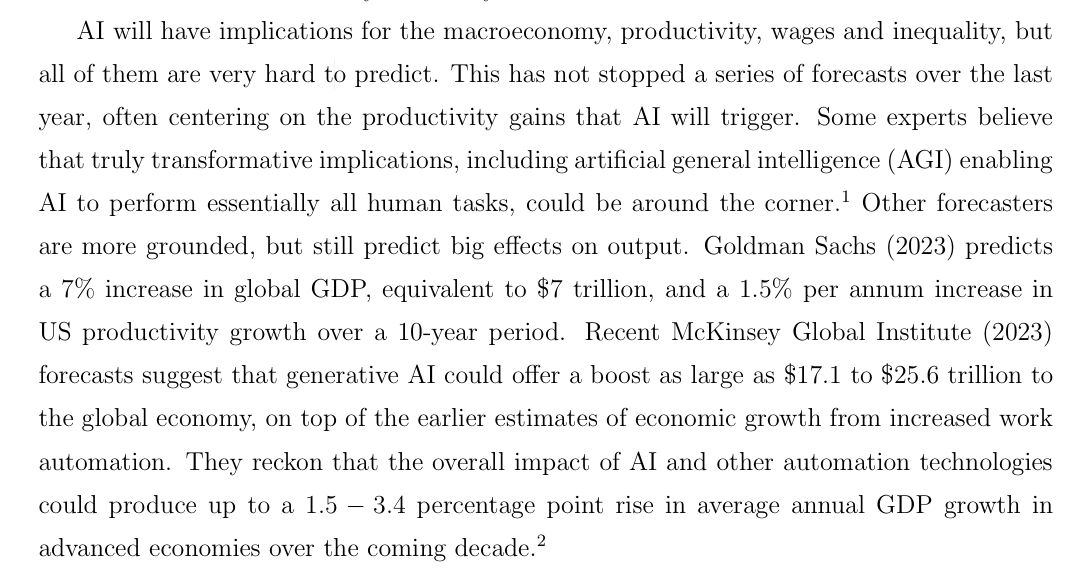
Does this mean that we’re in an AI bubble? Not necessarily. Only that AI by itself apparently doesn’t hugely lift the overall U.S. economy (a huge part of which is government spending/welfare state!). We’ve got about 1.5% per capita real GDP growth right now. Maybe that includes the AI lift? This NBER paper by a Nobelist (sort of) predicts minimal per capita growth, but cites estimates as high as 3.4 percent per year as the boost (nowhere close to the 10% we’d need to get out debt down to Taiwan’s relative level):

(He cites McKinsey, the giant brains behind Enron!)

The only way to make $40 trillion in debt insignificant, therefore, would be to grow the U.S. population to about 1 billion humans at roughly the same level of skill/income as the current U.S. population. Until Donald Trump showed up (again!), our wise politicians were working on this, but they forgot to apply and skills test for immigrants.

(In case this blog post is going to be a source for an NPR or PBS story (example), let’s not forget that both Turing and Bessent were/are members of the 2SLGBTQQIA+ community.)

Full post, including comments
Even companies worth $1 trillion don’t want to pay Nvidia’s prices

I hope that everyone has made tons of money taking my investing advice and doing the opposite. Loyal readers may remember that I’ve been skeptical of Nvidia becoming worth more than all of the European Union combined and, therefore, never purchased NVDA (current market cap: $5+ trillion). My theory was that 50 percent profit margins for Nvidia would motivate other companies to develop chips and then the AI nerds would recompile their code (or ask AI to recompile their code). Google did this a long time ago with its Tensor Processing Unit. Intel tried and apparently failed with Gaudi (but they were very successful in DEI!). Elon Musk has his AI5 chip and, eventually, his own fab.

OpenAI is the latest entrant into this mix, apparently. “OpenAI Claims Its New Chips Can Outperform Nvidia Processors in Tests” (Bloomberg, yesterday):

The company plans to start using the new chips to support its artificial intelligence models later this year, which should significantly reduce costs for OpenAI as it rolls out more widely.

OpenAI, losing enough money every year to be worth almost $1 trillion, created Jalapeno in a partnership with Broadcom Inc., which makes custom chips for a variety of clients. The two companies, which announced their pact last year, touted the speed at which the processor was developed in June, saying it came together in record time.

Even if this thing succeeds, there will still be a huge market for Nvidia, apparently:

Jalapeno wasn’t tested against the new generation of Nvidia chips, Vera Rubin, which just began shipping. It’s also not designed for training AI models, an area where Nvidia technology excels. Jalapeno is intended for the inference phase of AI — the stage when models have already been trained and can begin responding to prompts and handling tasks.

(Why is the chip named for Vera Rubin, someone who was neither an electrical engineer nor a software developer? Google AI:

Honoring Women in STEM: The company has a specific practice of naming key platforms after pioneering women scientists. Previous examples include Grace Hopper (the Grace CPU) and Ada Lovelace (the RTX 40-series architecture)…

I guess we can’t expect the William Shockley CPU/architecture any time soon, despite the man’s Nobel for the invention of the transistor, but why not one for Jack Kilby? Kilby died in 2005, prior to the full flowering of Rainbow Science, and therefore Kilby’s gender ID is unknown (we could say the same regarding Vera Rubin, who died in 2016, some years before the trans-enhanced Rainbow Flag flew at the White House))

How much do journalists and editors need to know about electrical engineering in order to cover cutting-edge AI hardware?

Because the chip is achieving strong results at low voltage — 700 watts — Jalapeno will allow OpenAI to save money when running its data centers, where power is a key cost, he said.

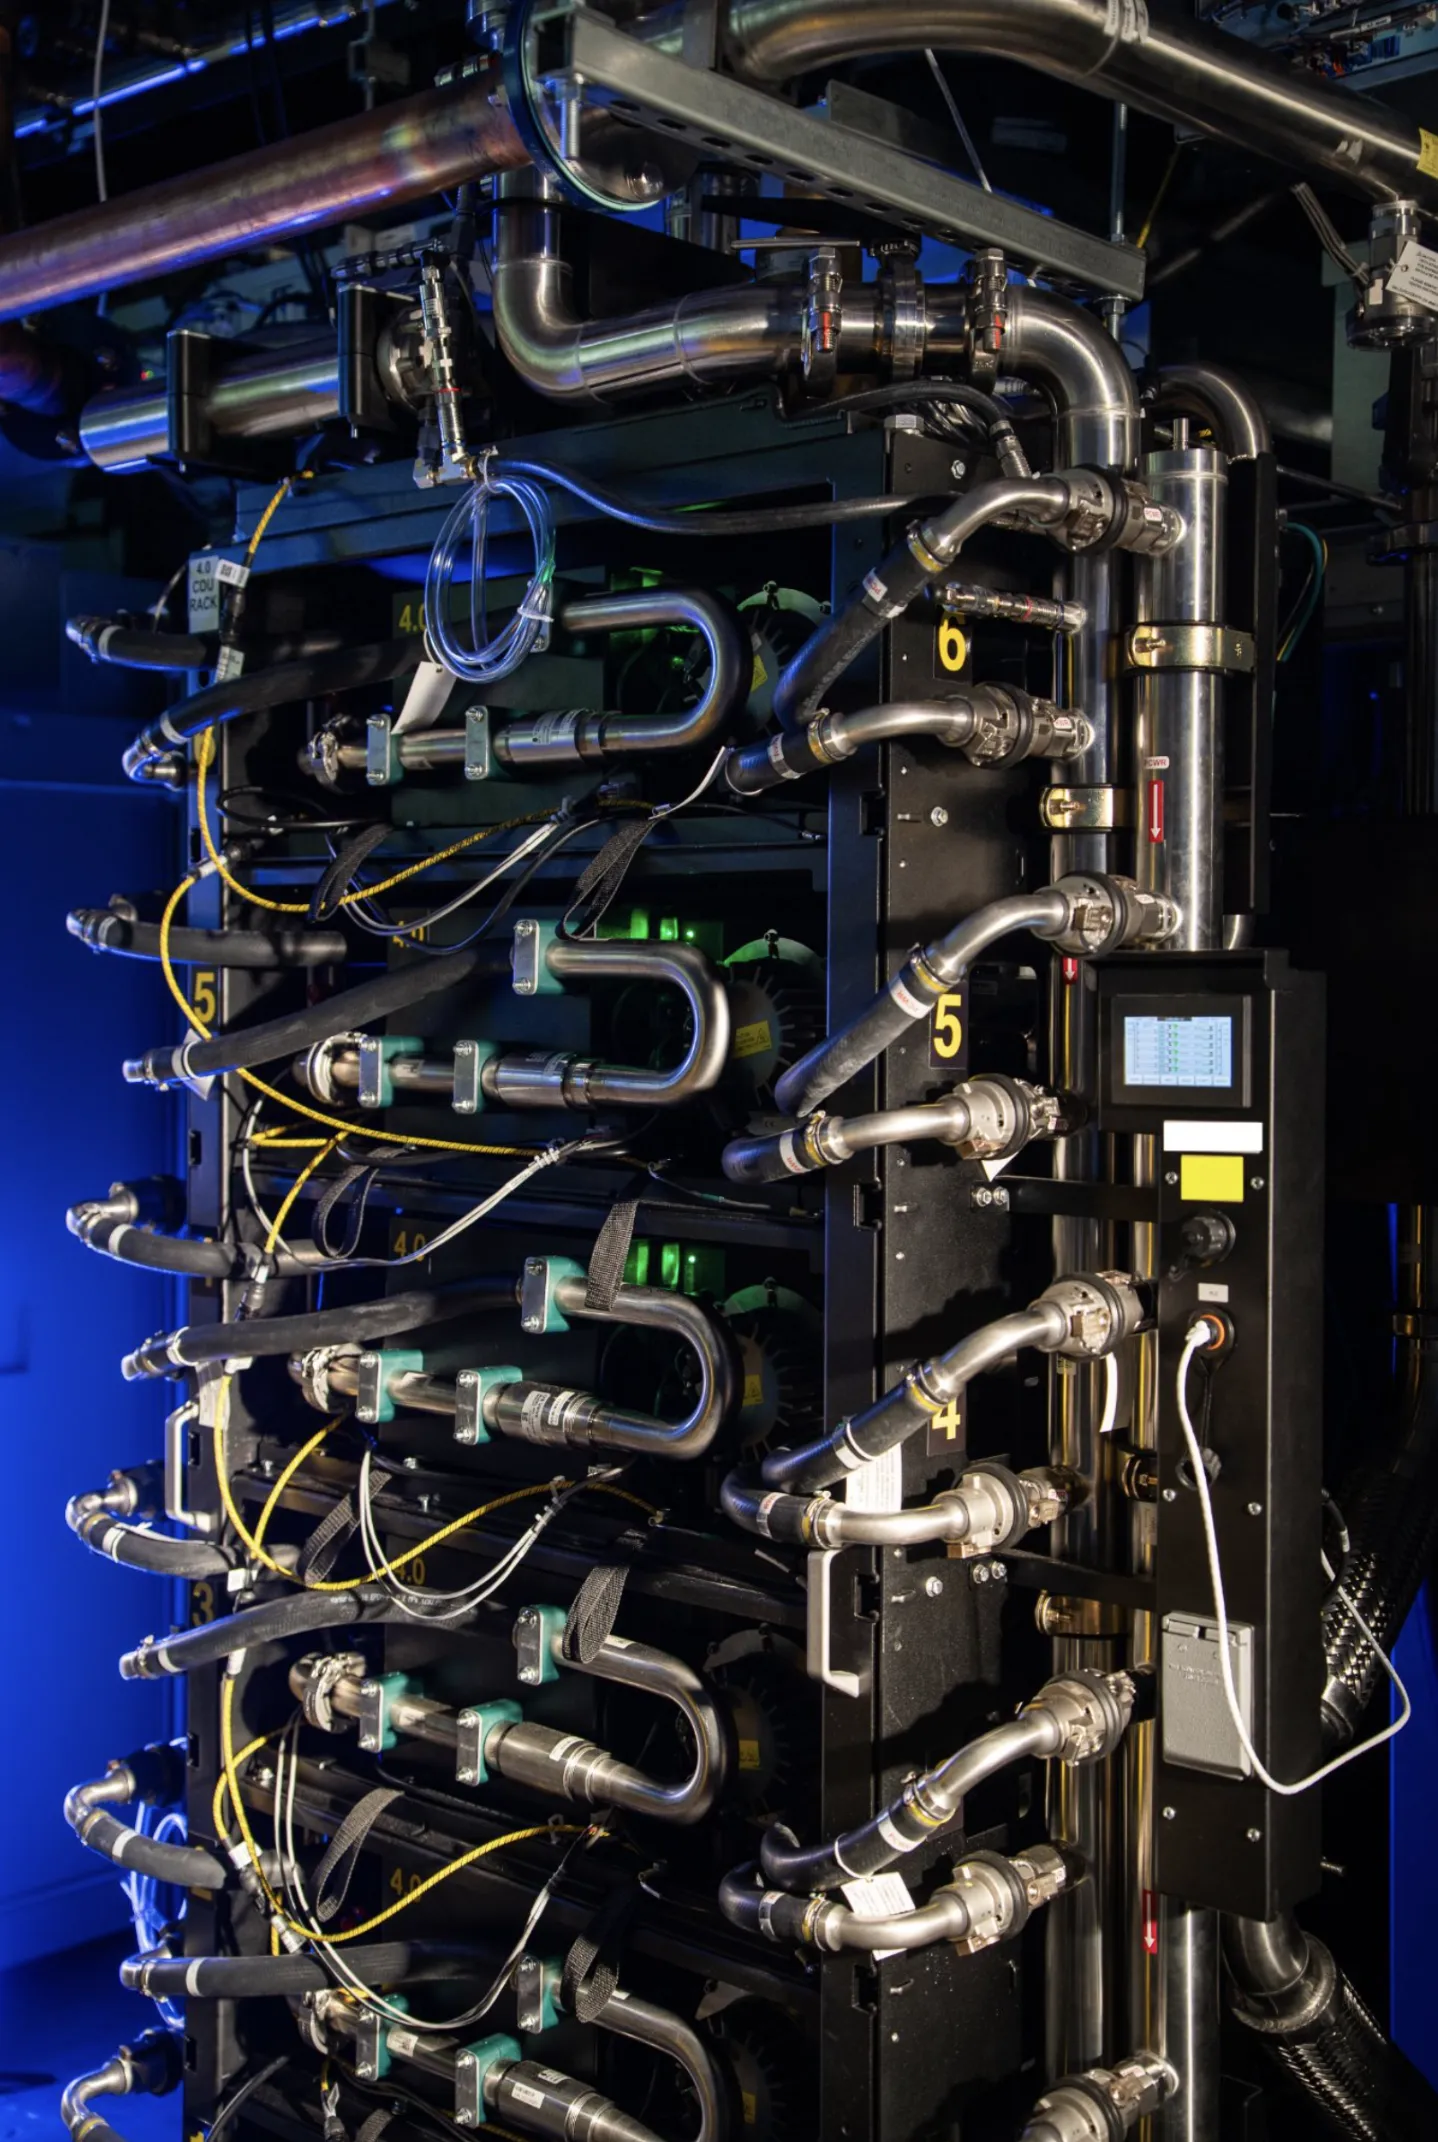
Speaking of high voltage, let’s have a look at the cooling system for Google’s latest TPUs (blog entry, which Google’s massive AI brain couldn’t figure out should have a date on it; I think it is from April 2026):

It looks like they got retired Pratt PT6 engineers to work on this!

(Actually, this suggests a career path: instead of fighting it out on the crowded software front, a young person could study to become a packaging/cooling engineer.)

Vaguely related… let’s see if we can figure out where Nvidia’s passion for “Honoring Women in STEM” comes from. Perhaps nerds identifying as “women” were the principal designers of Nvidia’s hardware and software?

Prompt to Gemini (to run on Google’s TPUs so that the results aren’t biased by running on Nvidia chips):

Who were the principal engineers of Nvidia’s historically important GPUs and software architectures, including CUDA? In other words, who are the people who are primarily responsible for making Nvidia as valuable as it is today?

Answer (not in quote style):

Key Technical Leaders Behind Nvidia’s Rise

1. Curtis Priem & Chris Malachowsky (Co-Founders & Founding Hardware Architects)

  • The Role: Co-founded Nvidia in 1993 alongside Jensen Huang.
  • Their Contribution: Priem was the chief architect of Nvidia’s early graphics chips (including the NV1 and the breakthrough RIVA 128), while Malachowsky led system engineering and hardware design operations.
  • Impact: They established Nvidia’s core hardware engineering practices and designed the early pipelines that allowed Nvidia to survive the “3D accelerator wars” of the late 1990s and create the original GeForce 256—the chip Nvidia marketed as the world’s first true “GPU.”

2. Dr. David Kirk (The “Father of CUDA” & Chief Scientist 1997–2009)

  • The Role: Chief Scientist and VP of Architecture.
  • Their Contribution: David Kirk was the primary visionary behind transforming Nvidia’s fixed-function 3D graphics hardware into programmable, general-purpose parallel processors.
  • Impact: In the mid-2000s, Kirk persuaded Jensen Huang to mandate that every single Nvidia GPU include dedicated general-purpose execution units—a massive financial gamble at the time. This decision laid the groundwork for CUDA (Compute Unified Device Architecture), launching general-purpose GPU computing (GPGPU) and making GPUs usable for scientific computing and later AI.

3. Ian Buck (VP of Accelerated Computing & Original CUDA Architect)

  • The Role: Creator of the BrookGPU programming language (at Stanford) who joined Nvidia to lead the CUDA project.
  • Their Contribution: While pursuing his PhD at Stanford, Buck created Brook, an extension of C for streaming coprocessors. Jensen Huang hired Buck to lead the software and systems team that built the original CUDA software stack and runtime environment, released in 2006.
  • Impact: Buck turned the raw, complex parallel hardware engineered by Kirk’s team into an accessible software platform for C/C++ developers. Without Buck’s software stack, AI researchers in 2012 (like Alex Krizhevsky and Geoffrey Hinton) would not have been able to train AlexNet on Nvidia GPUs—the spark that triggered the modern deep learning boom.

4. John Montrym (Chief Architect, GeForce/Tesla Architecture)

  • The Role: Senior Architect and Fellow.
  • Their Contribution: Montrym was a key architect behind the NV40 (GeForce 6 series) and the landmark G80 (Tesla architecture) released in 2006.
  • Impact: The G80 was the first unified shader architecture in a PC GPU and the hardware home where CUDA was born. It abandoned separate vertex and pixel pipelines in favor of unified streaming multiprocessors (SMs), setting the blueprint for every modern GPU architecture designed since.

5. Jonah Alben (Senior VP of GPU Engineering)

  • The Role: Longtime leader of Nvidia’s hardware silicon development.
  • Their Contribution: Alben joined Nvidia in 1997 and has spent over two decades directing the physical architecture, design execution, and engineering teams behind generations of GPU microarchitectures: Fermi, Kepler, Maxwell, Pascal, Volta, Ampere, Hopper, and Blackwell.
  • Impact: Alben’s team managed the scaling and execution challenges as GPUs grew from millions to over 200 billion transistors on single silicon packages. His team integrated specialized hardware engines directly into the GPU pipeline—most notably Tensor Cores (introduced in Volta/Ampere) and Transformer Engines (in Hopper/Blackwell)—which gave Nvidia a 10x-100x efficiency advantage in AI workloads over traditional CPUs and competing chips.

6. Dr. Bill Dally (Chief Scientist & Head of Nvidia Research)

  • The Role: Former Chairman of Stanford’s CS Department, appointed Nvidia Chief Scientist in 2009 (succeeding David Kirk).
  • Their Contribution: A pioneer in computer architecture and high-speed interconnect networks, Dally leads Nvidia’s long-term research division.
  • Impact: Dally pivoted Nvidia’s research toward optical interconnects, low-precision AI math (FP8, FP4 formats), ray tracing hardware cores (RT Cores), and multi-chip network scaling (NVLink). His architectural research predicted the massive bandwidth bottlenecks of large AI models years before ChatGPT emerged.

You can see the full answer and also one from Grok.

Fun fact from Oshkosh/AirVenture 2026: I ran into a mid-level Nvidia employee. He had shown up in his new airplane, a perfectly restored P-51 Mustang ($5 million?).

Full post, including comments
ChatGPT, roof warranty analyst

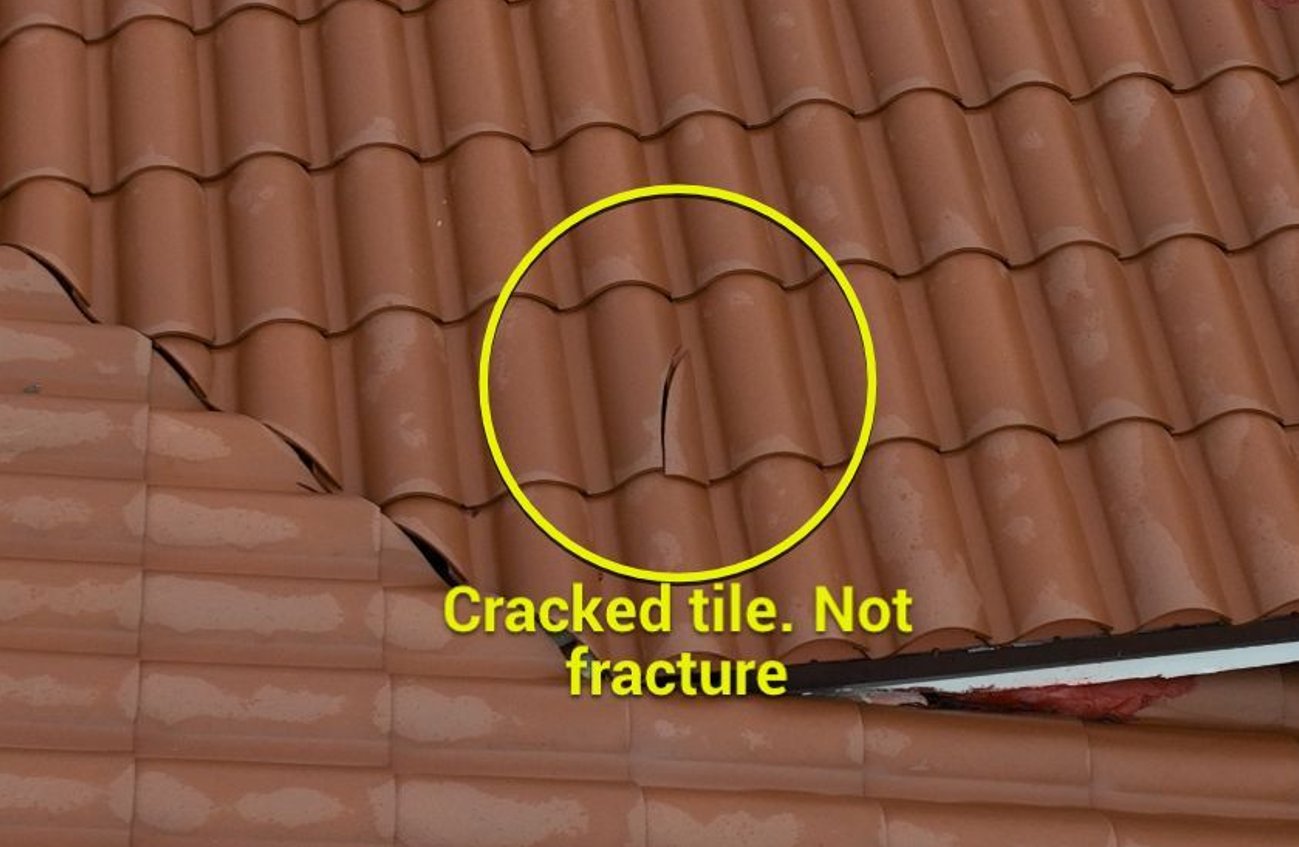
Our clay tile roof was installed a year ago and came with a 7-year warranty with the following condition: “All warranties require free annual maintenance inspections, in order to maintain validity throughout the duration.” During this year’s inspection, done by drone because the roof was slightly wet and clay is extremely slippery/hazardous when wet, a cracked tile was discovered.

The roofer has to fix this at no charge? Email from the roofer: “Clay tiles will not crack like concrete tiles since they aren’t absorbing water and would only crack from impact of some kind.”

There haven’t been any real wind storms here in the past year (the last “major hurricane” in Palm Beach County was in 1949). The cracked tile isn’t near a coconut palm that could have dropped a heavy nut onto it. I uploaded the photo to my warranty analyst (ChatGPT):

The crack looks more like a structural/installation crack than a classic impact break. It is a fairly clean, narrow crack running longitudinally through the tile, without an obvious crater, chip, crushed spot, or radiating fracture pattern where something struck it. Impact from something substantial—fallen branch, tool, golf ball, worker stepping hard on an unsupported portion—often leaves some evidence at the point of contact.

On a one-year-old roof, plausible non-impact causes include a hairline crack present when installed that subsequently opened up; a tile stressed by its nail/screw/clip or adhesive; inadequate support beneath part of the tile; somebody walking on it during installation or later work; or occasionally a manufacturing defect.

(I’m pretty sure that we’ll still have to pay the roofer to fix the problem that his crew created, or maybe that the tile manufacturer (Verea in Spain (maybe they’re too busy freeing “Palestine” to go the last kilometer in quality control?)) created, but at least now we know that we’re being cheated!)

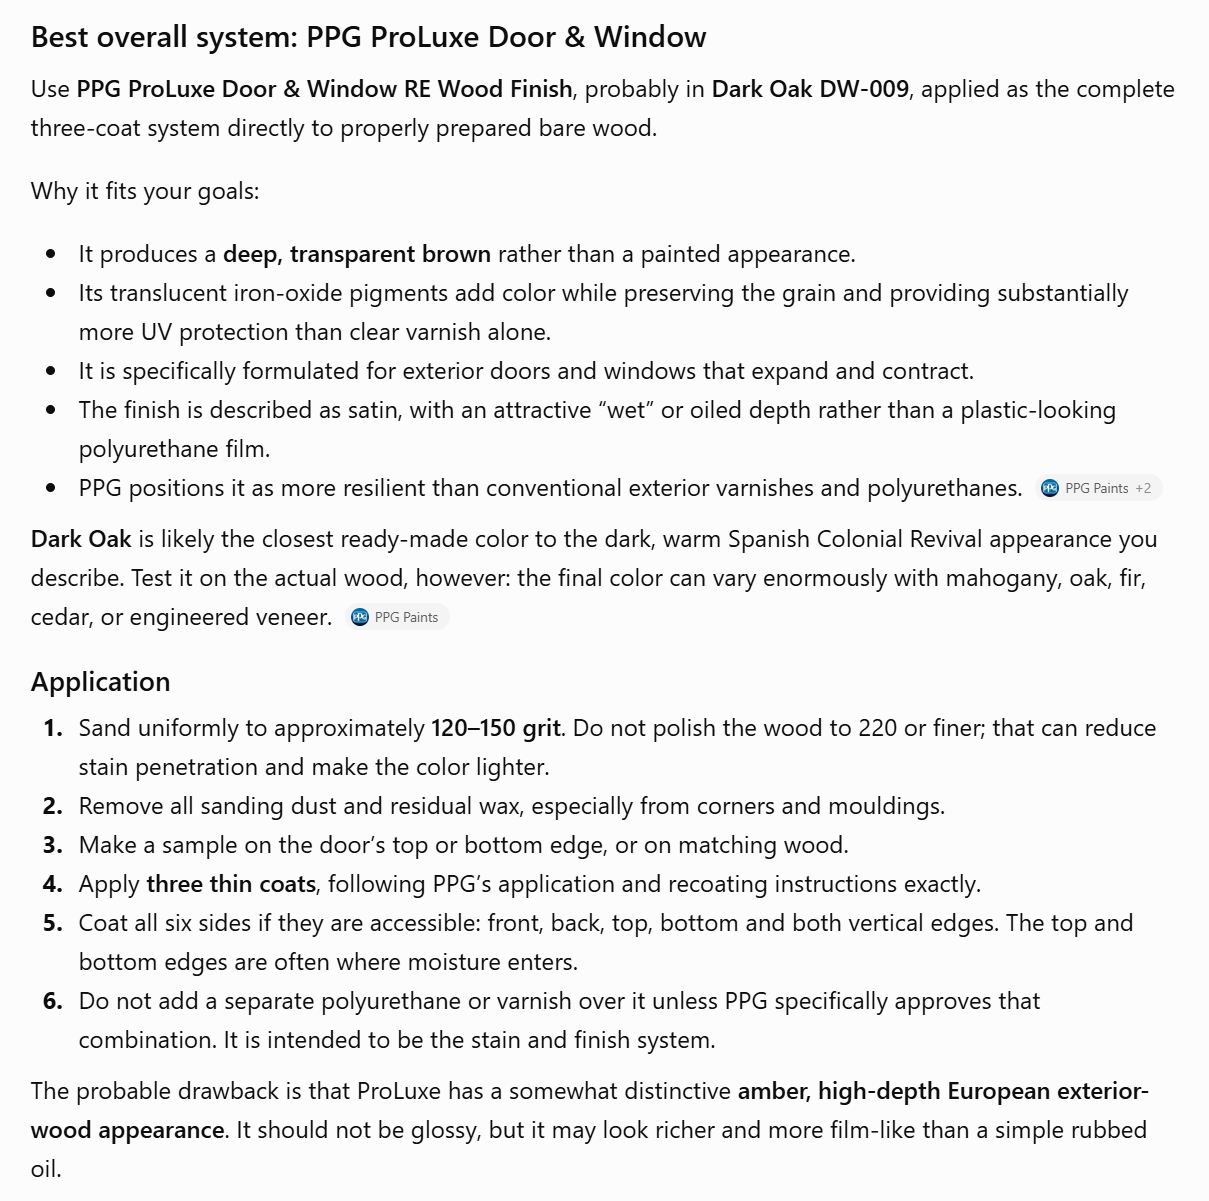
Also at the intersection of AI and Florida homeownership, I asked ChatGPT about what stain to use for the front door, beginning to look a bit shabby. Absent AI, I would have tried to buy Sikkens, making stain in the Netherlands since pre-Islamic times (1792). ChatGPT had a different perspective:

I bounced the question to Grok and Claude and learned… that Sikkens in the U.S. is marketed as “PPG”. The AI was still useful, though, potentially, because it calculated how many quarts are needed and that there is a specific stain for doors as opposed to siding.

Full post, including comments
Would ChatGPT have hired Jason A. K. Arday?

It’s Academic Integrity Day here on this blog… (see Plagiarist Claudine Gay getting paid $3.1 million/year after “resigning” from Harvard)

The smartest people in the Islamic Republic of the UK hired Jason A. K. Arday to hold a professorship at Cambridge University in 2023, which is a huge appointment (what we call “assistant professors” they call “mere lecturers”). He’s been in the news recently for Claudine Gay-style plagiarism combined with an unusual life story. From “Icarus in the Faculty Lounge” (The Atlantic):

According to a cover letter that his agent sent to publishers at the time [2023], Arday’s book, to be titled Great and Unfortunate Things, would be “an awe-inspiring tale of near mythic proportions.”

That now appears to be an understatement. Arday’s story was indeed astonishing: As a toddler, he was diagnosed with autism and developmental delays; he didn’t fully speak until the age of 11; he learned to read and write only as an adult. Arday’s parents are Ghanaian immigrants [enrichers!]

Arday’s grad-school alma mater, Liverpool John Moores University, which first received direct complaints about the dissertation last fall, did its own investigation and cleared Arday of wrongdoing. “A confidential procedure was conducted,” the university told me in a statement. “Professor Arday’s PhD still stands.” But some of Arday’s other academic papers had potential problems too—and they seemed much worse than the mere borrowing of language. Quotes from structured interviews that Arday claimed to have performed closely resembled those used by other researchers; parts of some interview responses also reappeared across different studies under Arday’s name, attributed to different people. This duplication, if deliberate, would be something other than plagiarism—it would be academic fraud.

Might this be Donald Trump’s fault?

Some of the people who were going after Arday had a political agenda. Cofnas, the philosopher who put Arday’s dissertation through a plagiarism checker last month, argues for a “hereditarian revolution” based on the idea that innate differences in intelligence and other traits exist across racial groups. (He also claims that “the humanities and much of the social sciences have been slain on the altar of DEI.”)

Everyone loves an abuse survivor:

The doctors who assessed him as a toddler told his mother that “there’s no one in there” and that he was “no better than a vegetable.” Even his speech therapist wasn’t optimistic that he’d ever learn to talk. (At one point, she also physically abused him, the memoir says.) As a boy, Arday rocked and hummed and banged his head until he bled; he slammed cupboard doors and smeared his feces on the walls. Yet still, eventually, he started to verbalize.

Arday is nearly deaf in one ear; he’s dyslexic; he finds simple math befuddling; he has “marked difficulties” with memory, reading, and processing skills. As a teen, he was beaten so severely by a group of kids his age that he became an epileptic. To make his way through secondary school while—by his own account—illiterate, he needed ample help: support assistants who sat beside him in class and took notes on his behalf.

(What good are “notes” if a person is “illiterate” (unable to read)?)

By the time Arday started on his master’s degree, he writes, he was reading at about the same level as his 3-year-old daughter.

Money was tight, so after each day of teaching, Arday writes, he had to work an overnight shift in a supermarket, from 11 p.m. to 5 a.m., and then a morning shift as a cleaner from 5:30 to 7:30. The only time he had left to write his dissertation was when he was commuting between London, where he lived, and Liverpool, where he taught. On those semiweekly five-hour rides, the book explains, he would open up his laptop on the plastic seat-back table and start typing out his thesis, hunt-and-peck style.

As his dissertation deadline approached, Arday started having blurry vision; medical scans revealed a brain tumor. After it was removed, he had a ministroke and lost his short-term memory. “I’d worked on my thesis for over thirty months, and now I was reading it as if for the first time,” he writes. As one might expect, his thesis defense did not go smoothly. One examiner was suspicious of his work: “I am struggling to see that there is any original contribution here,” she said, according to the book. But Arday, who often likens himself to Rocky Balboa, managed to fight back, and in the end, he passed. (The memoir brings up the fictional boxer in about a dozen different contexts.)

(Note that Rocky is now a Florida resident (Journal of Popular Studies) and stopped paying taxes to Gavin Newsom in 2024)

More troubles follow in the years ahead: Arday’s brain tumor returns; he splits up with his wife; he suffers autistic burnout during the coronavirus pandemic and can’t get out of bed. He decides to kill himself by jumping off a bridge, but at the very last minute, he listens to his favorite song, “Take It to the Limit”—delaying his attempt just long enough for a member of his family to rescue him. “In the end,” he writes, “my decision to listen to the Eagles likely saved my life.”

I reached out to the book’s fact-checker [at Simon & Schuster] to ask whether this and several other stories from the book had been verified, but she did not respond. … the book’s release is still on track and that it has even been designated as an “Editors’ Pick” on Amazon

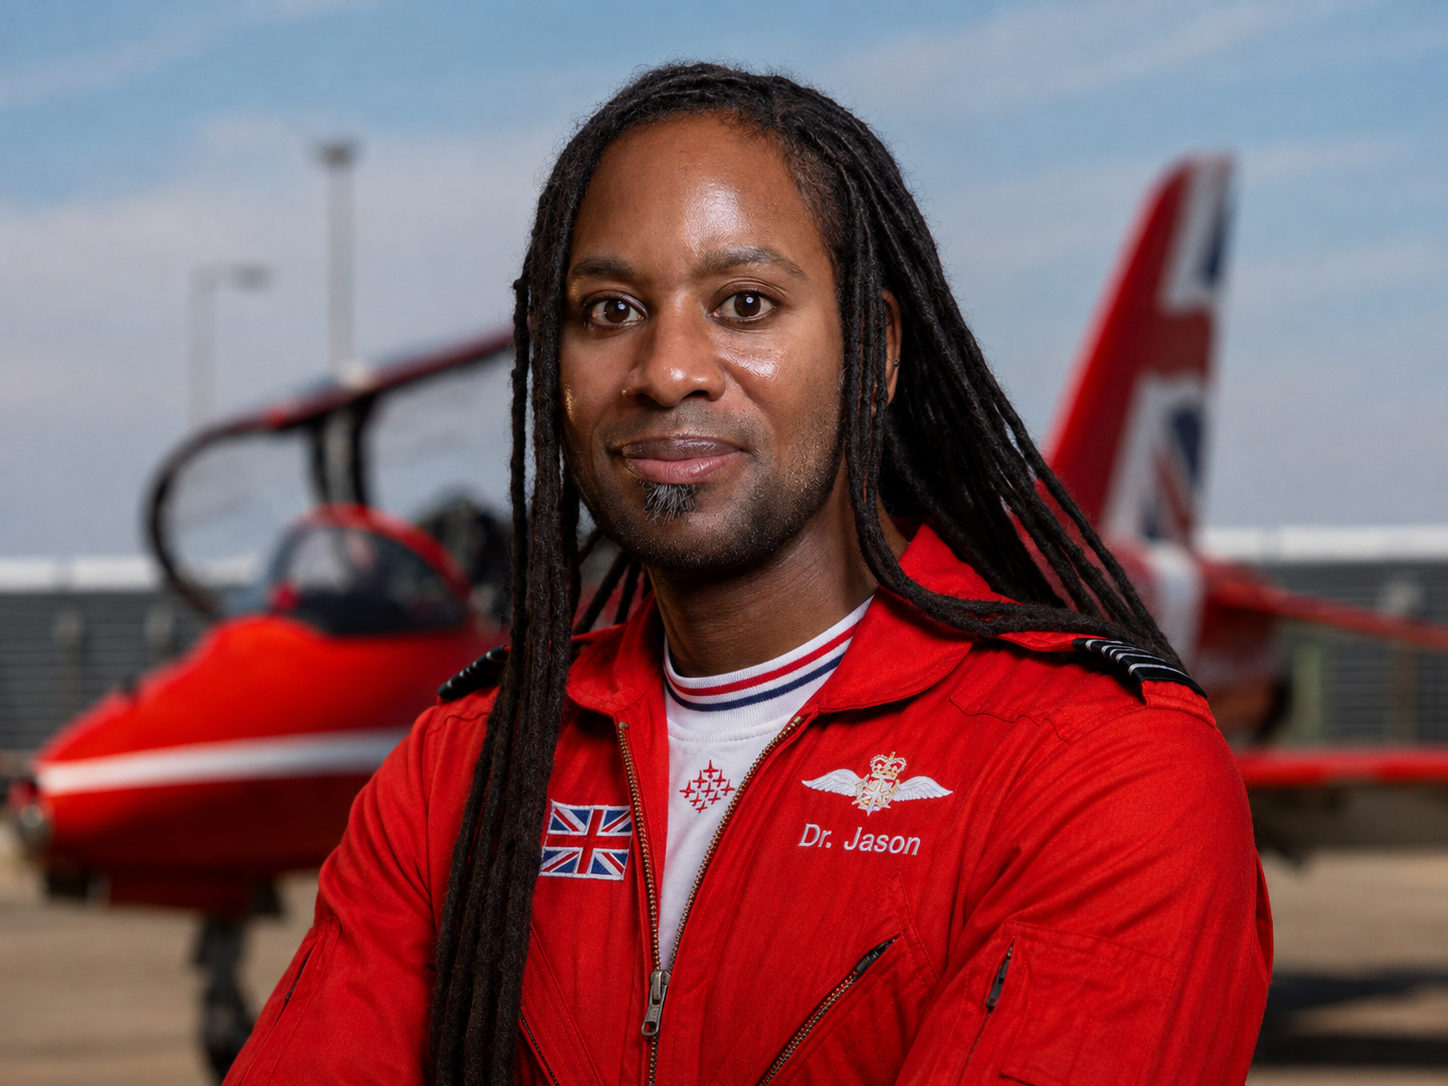
This wasn’t part of the book proposal, but it seems that Prof. Dr. Arday, Ph.D. was also an RAF Red Arrows pilot:

The Professor’s PhD thesis is available online. I downloaded it and asked ChatGPT to “evaluate the quality of research and writing”. Some excerpts from the full interaction:

The biggest problem is the sample and selection mechanism. There are only four intervention participants, selected from 46, and selection expressly included whether the candidates demonstrated characteristics that the researcher thought “resonated with the study’s aims and objectives” and a desire/capacity to improve their teaching. … More seriously, the researcher was a lecturer at the university attended by the subjects and already had relationships with them.

There is also no convincing counterfactual. There is:

no control/comparison group,
no random assignment,
only four highly selected subjects,
an intervention that the researcher helps facilitate,
and outcomes that are overwhelmingly based upon the subjects’ own narratives and perceptions.

The thesis itself eventually admits a crucial point: it cannot determine with certainty whether improved reflective practice would have occurred naturally rather than because of the peer-mentoring intervention.

Contribution to knowledge: This is probably the weakest part of the intellectual case for a PhD.

Writing quality: This is much easier to judge: the prose is substantially below the standard I would expect in the final, examined copy of a PhD thesis from a British university. The problems aren’t occasional typos. They’re pervasive. Even the title contains an erroneous apostrophe… Throughout the thesis there is a characteristic tendency to take a simple proposition and turn it into an elaborate nominalized construction. … Most problematic is the repeated use of inflated pseudo-technical expressions that obscure ordinary ideas.

The prose also affects the scholarship: This is more important than cosmetic proofreading. The convoluted language sometimes makes it difficult to determine exactly what proposition is being asserted and how strongly.

Should Arday have been given the big job at Cambridge?

Cambridge’s published criteria for its highest professorial level say that a Professor at Grade 12 should demonstrate: “outstanding achievement in research and research leadership assessed by reference to international levels of excellence”… Against that benchmark, Arday’s 2023 record looks unusually thin.

Cambridge’s February 2023 announcement … emphasizes his work on race … and, very explicitly, the importance of his appointment to Cambridge’s efforts to increase representation of people from disadvantaged and ethnic-minority backgrounds.

Asked to place Arday in a percentile of people in the same field, ChatGPT grudgingly estimates “somewhere around the 30th–50th percentile overall” (i.e., quite a few people with PhDs in education/sociology are far dumber than Dr. Arday!).

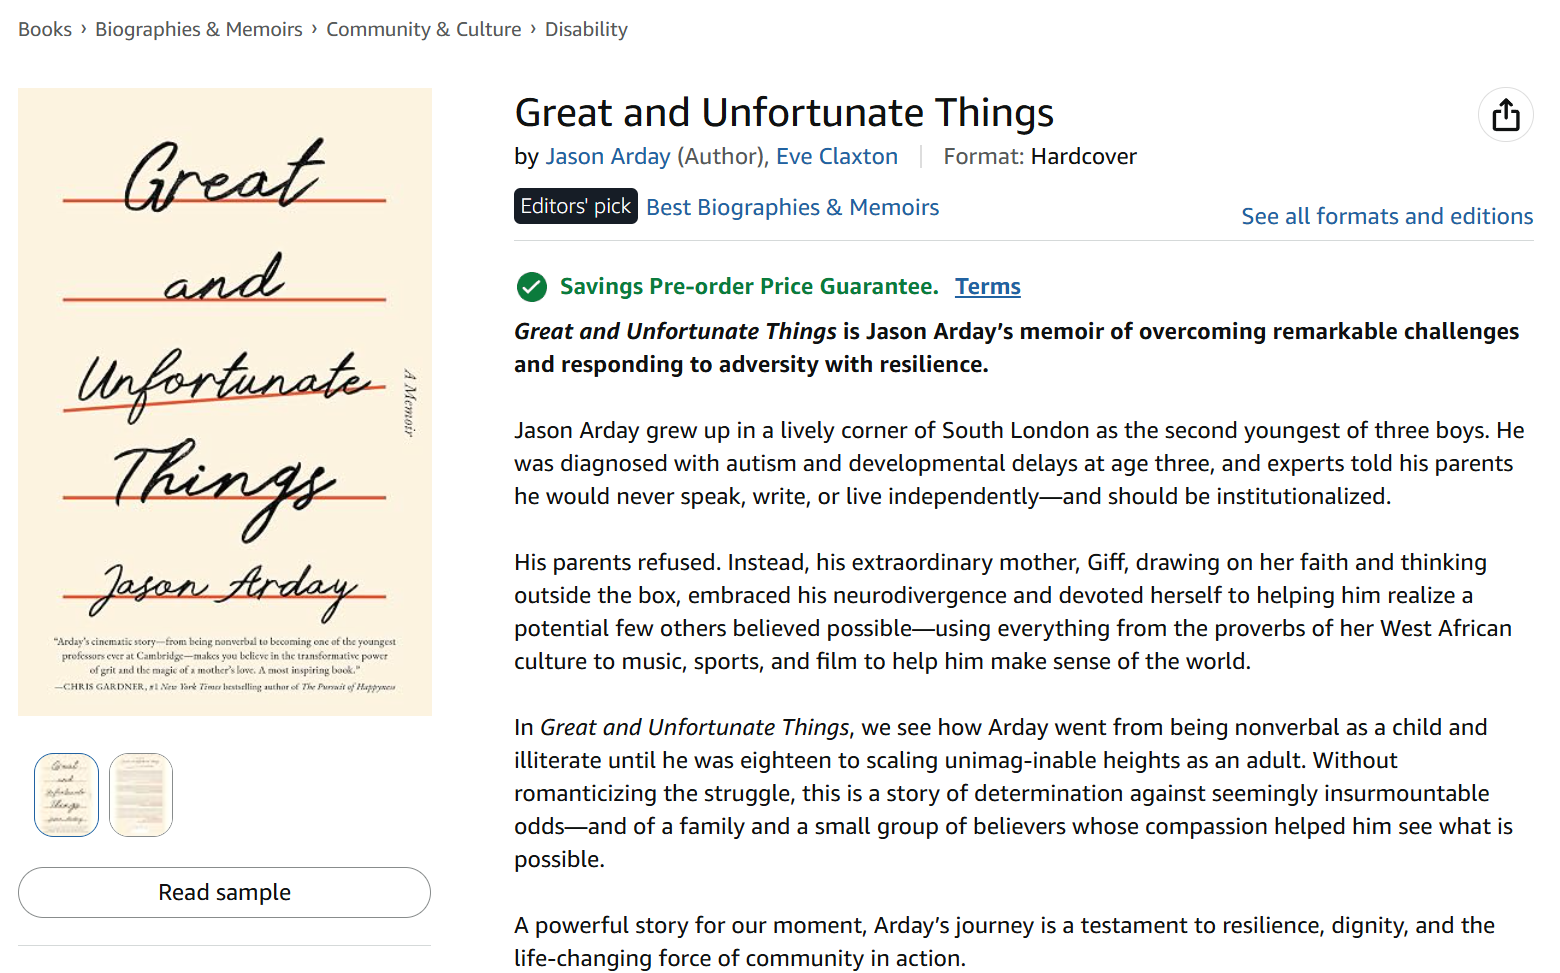
Here’s the Amazon page showing that this is, according to their experts in Seattle, among the world’s “Best Biographies & Memoirs”:

Throw out your Life of Johnson. It’s not among the “Best Biographies”.

Related:

  • “Jason Arday taught me. Here’s what I learned” (Fiona Brown in Unherd): “Before Arday arrived at Roehampton, university leaders enthusiastically told us of his amazing backstory: how he only learned to speak at 11 and write at 18, and how excited they were to have him teaching us. … I can honestly describe Arday’s teaching as terrible. He rarely used the PowerPoint slides. Instead, he usually sat casually on a desk, giving his generalized views on racism … Roehampton is a very diverse university, both in terms of racial background and neurodiversity, and takes inclusion seriously. More than two-thirds of the class were either black or from other non-white backgrounds. Most were women… In the end, Arday gave me 70% for my essay. That sounds good — except that my average for the year was 75%, meaning my overall result was dragged down. … In our meeting, I explained that 70% was a low mark for me and asked him to provide feedback. Suddenly, his friendly, confident demeanor changed. I now saw a side of him I’d never seen before: angry, but also scared. Arday implied that I was racist, and said that the only reason I wasn’t happy with 70% was due to my “white privilege”.”
Full post, including comments
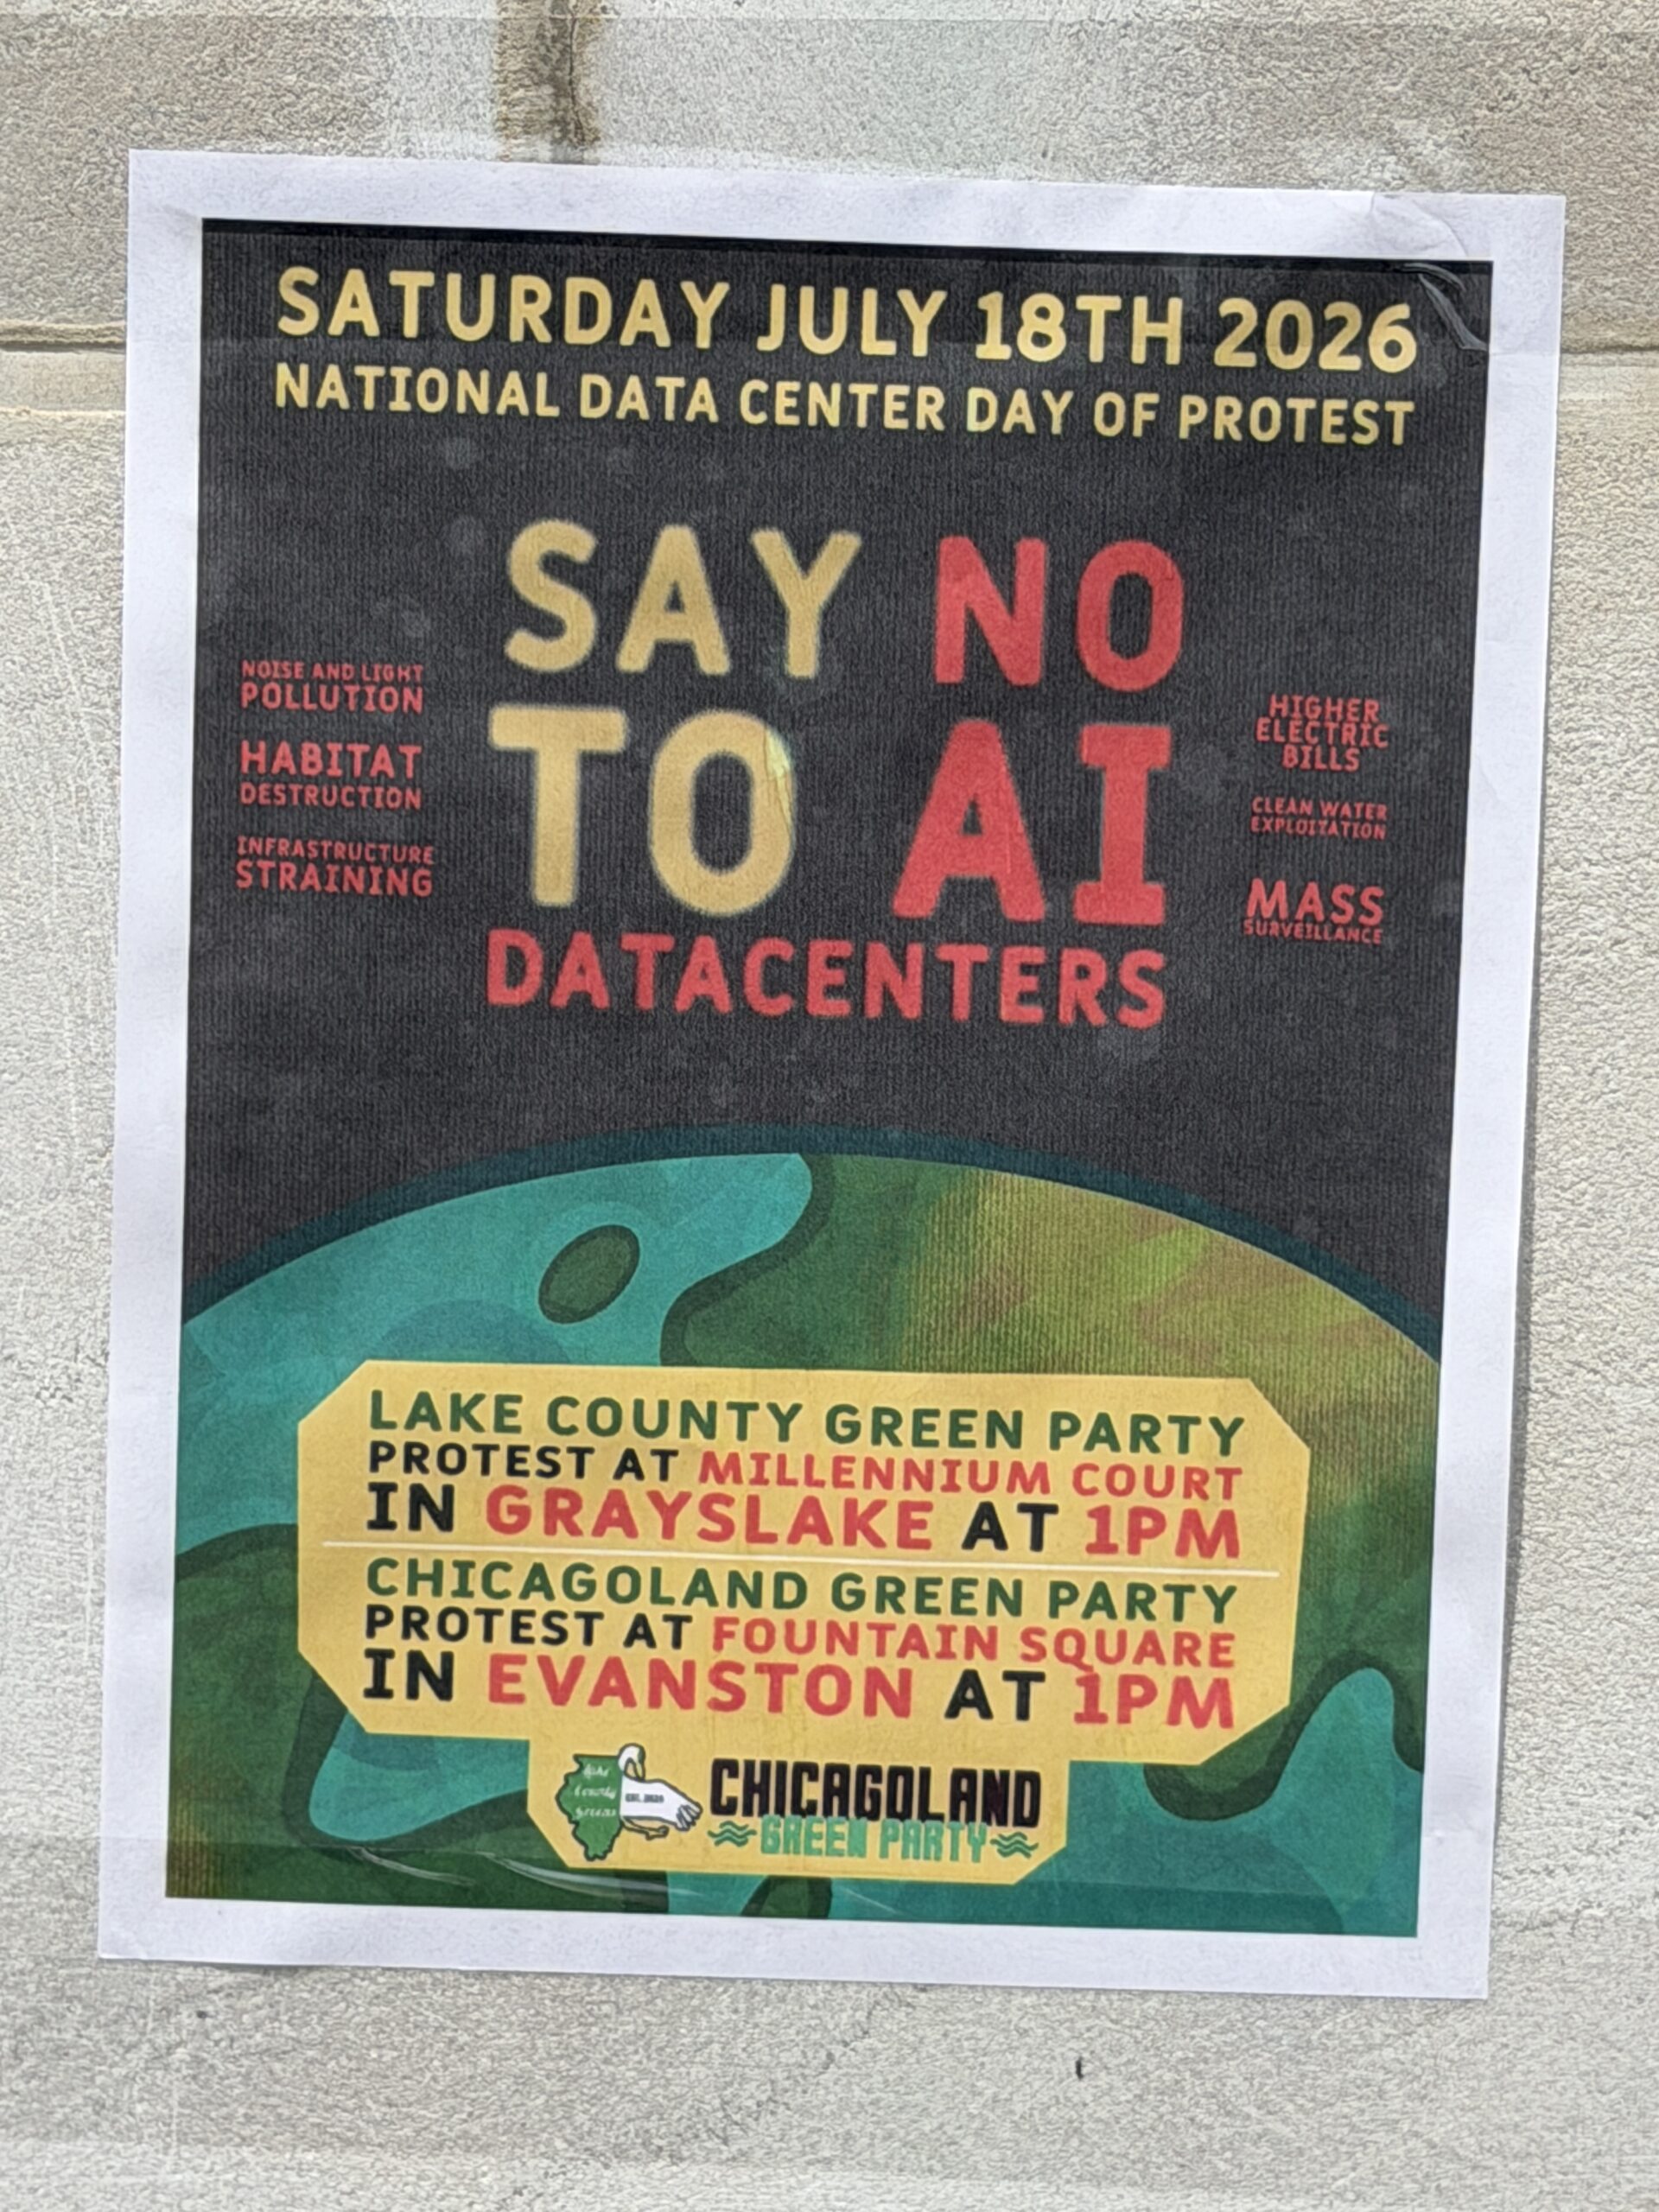
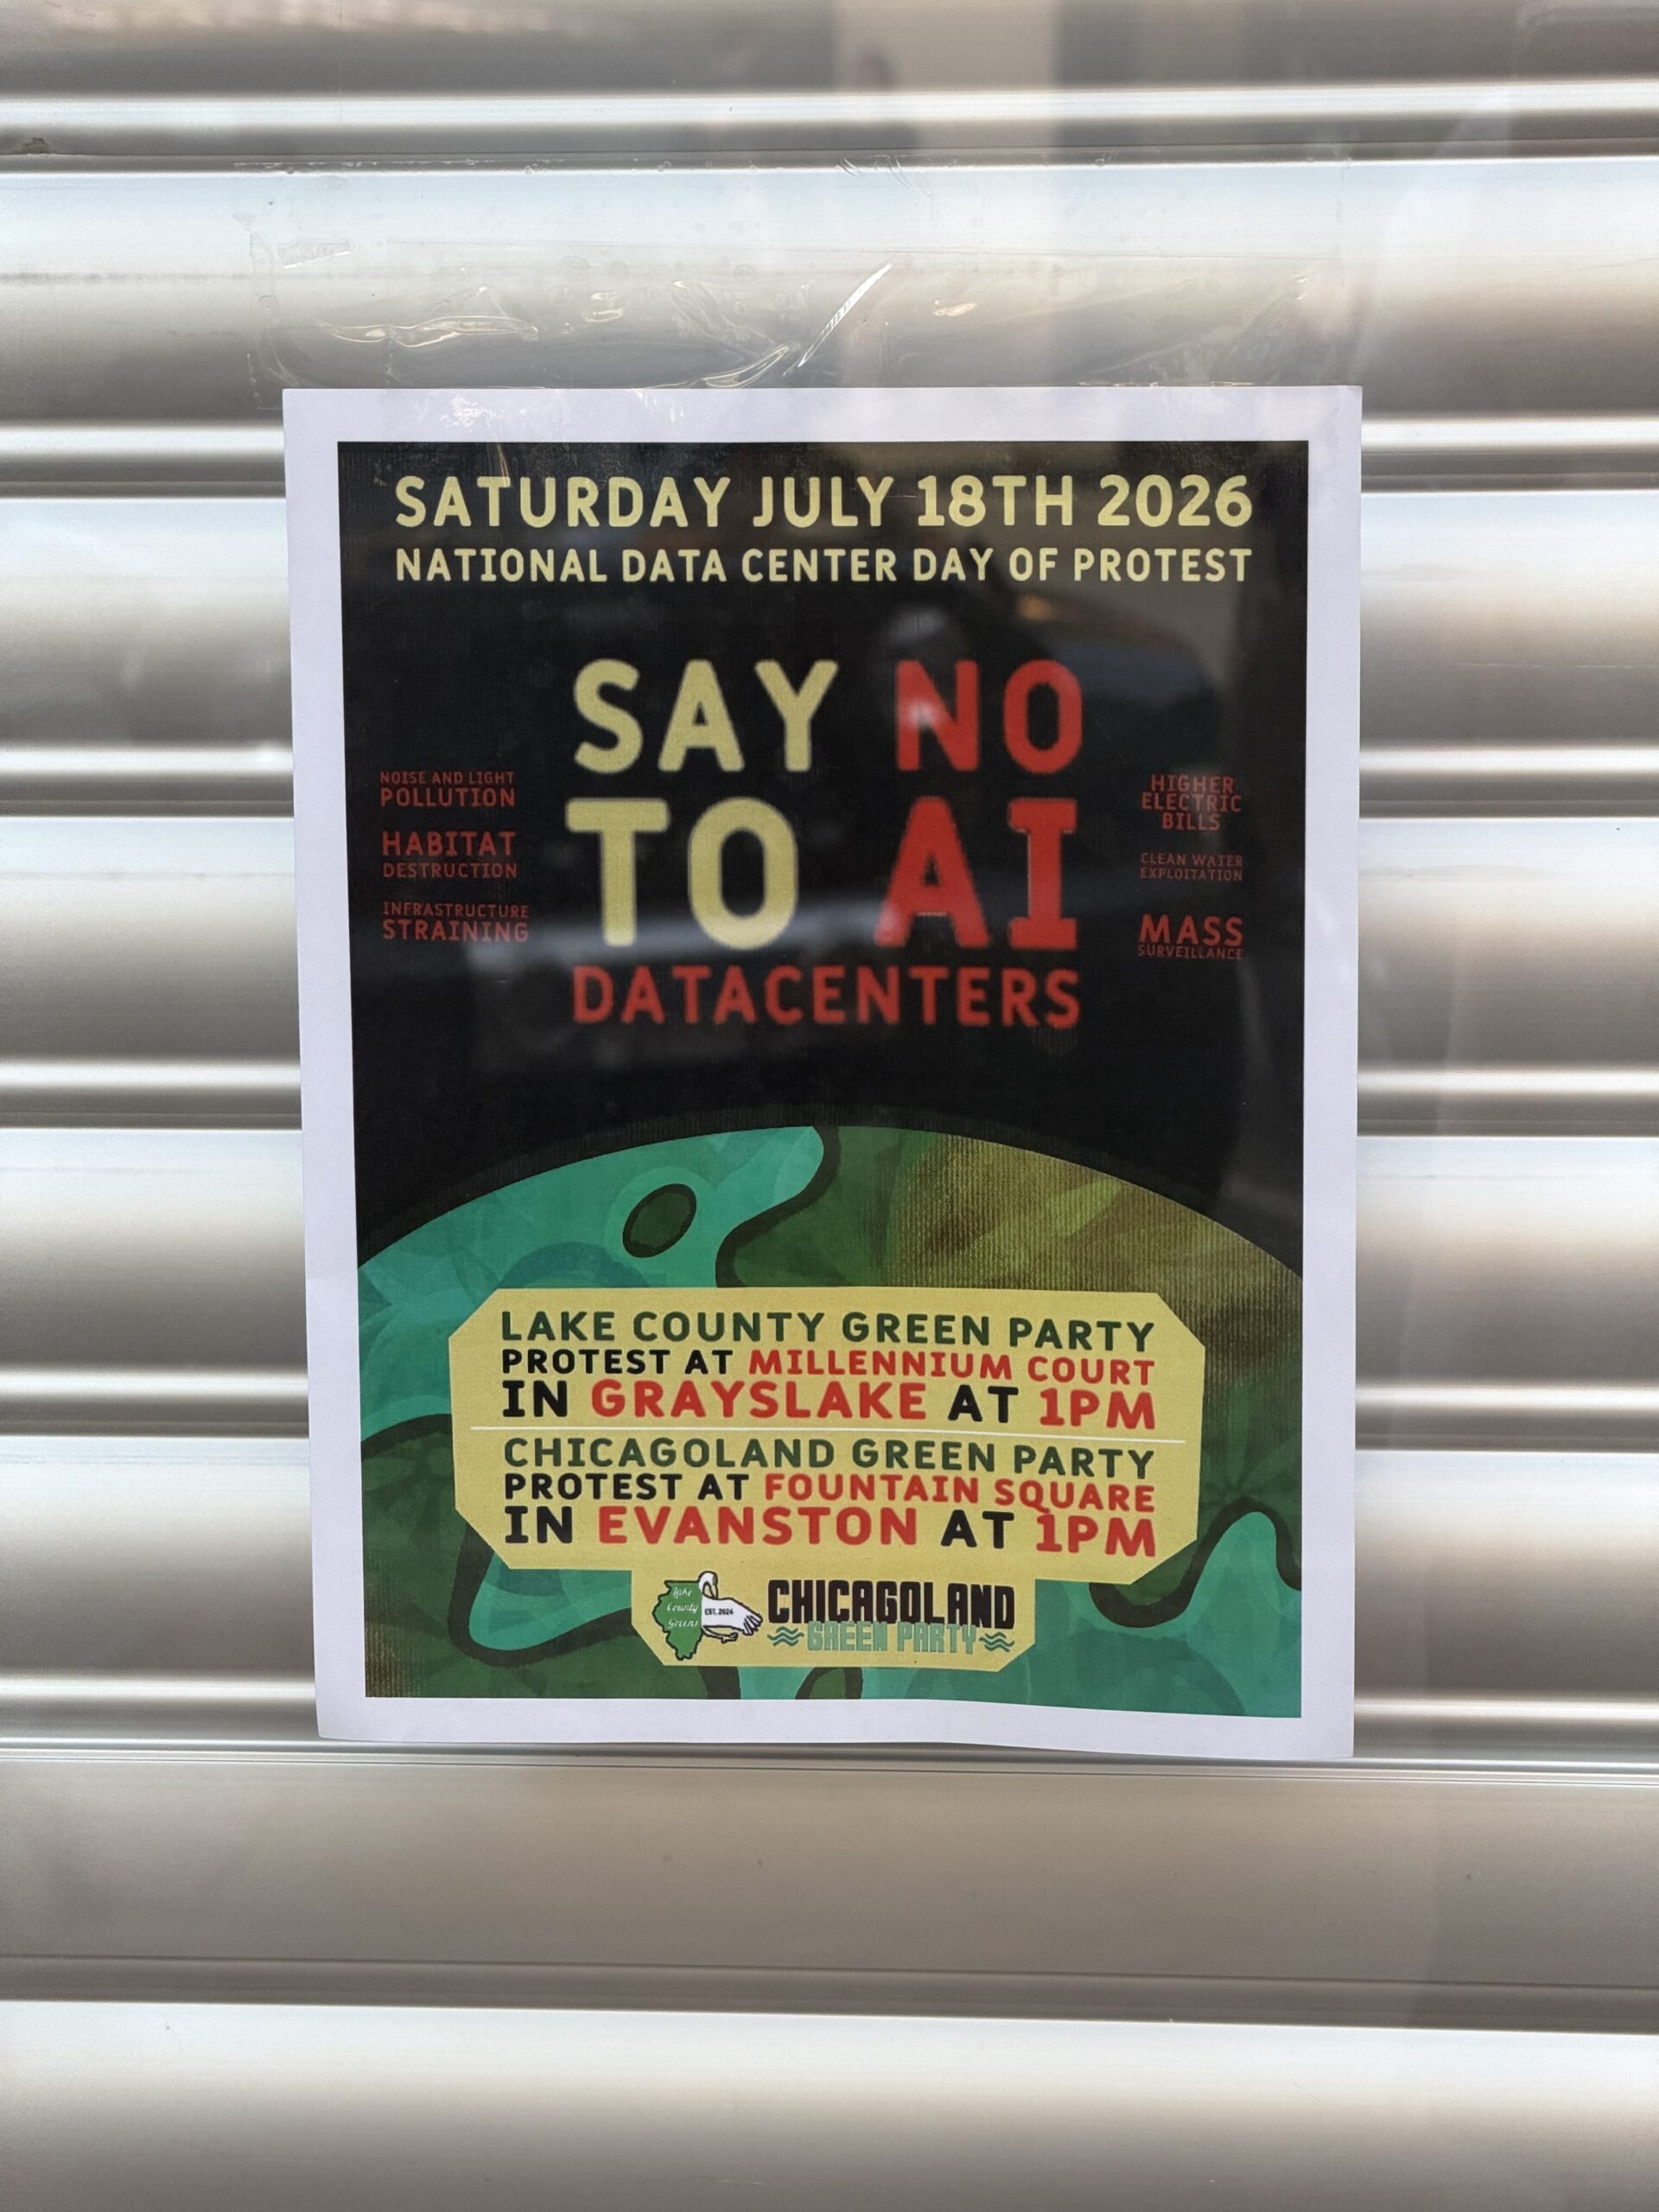
How’s your National Data Center Day of Protest going?

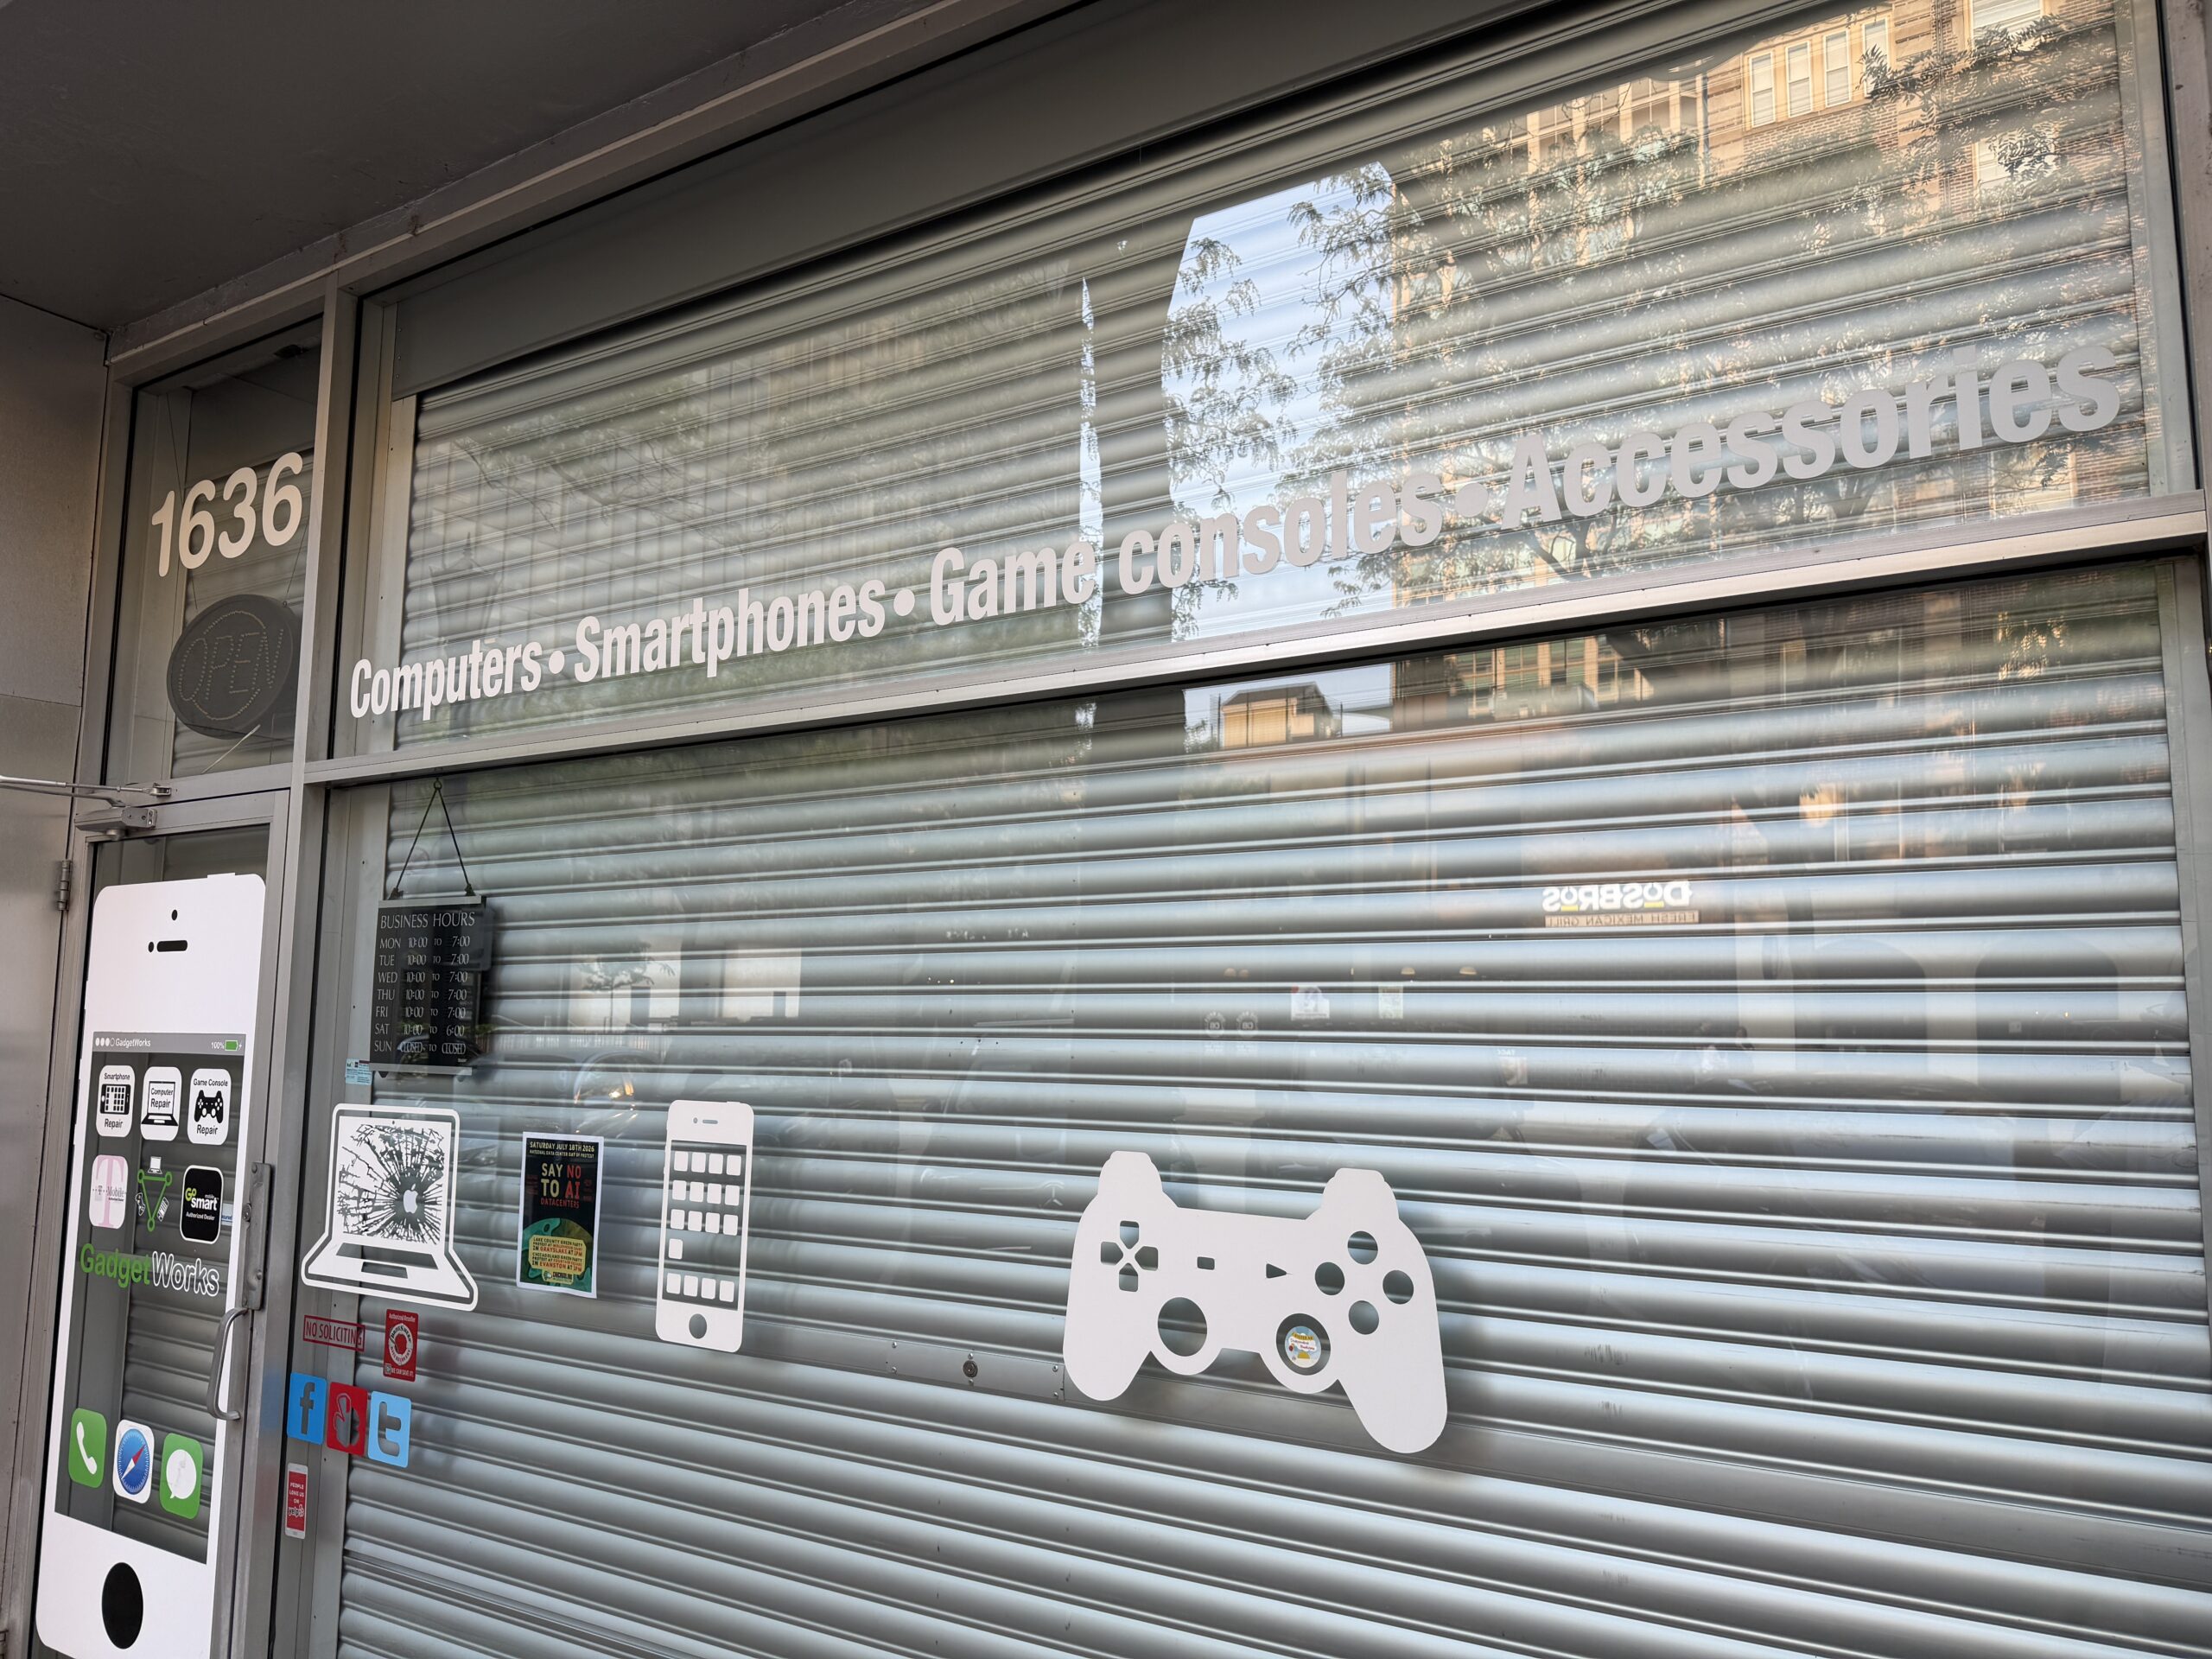
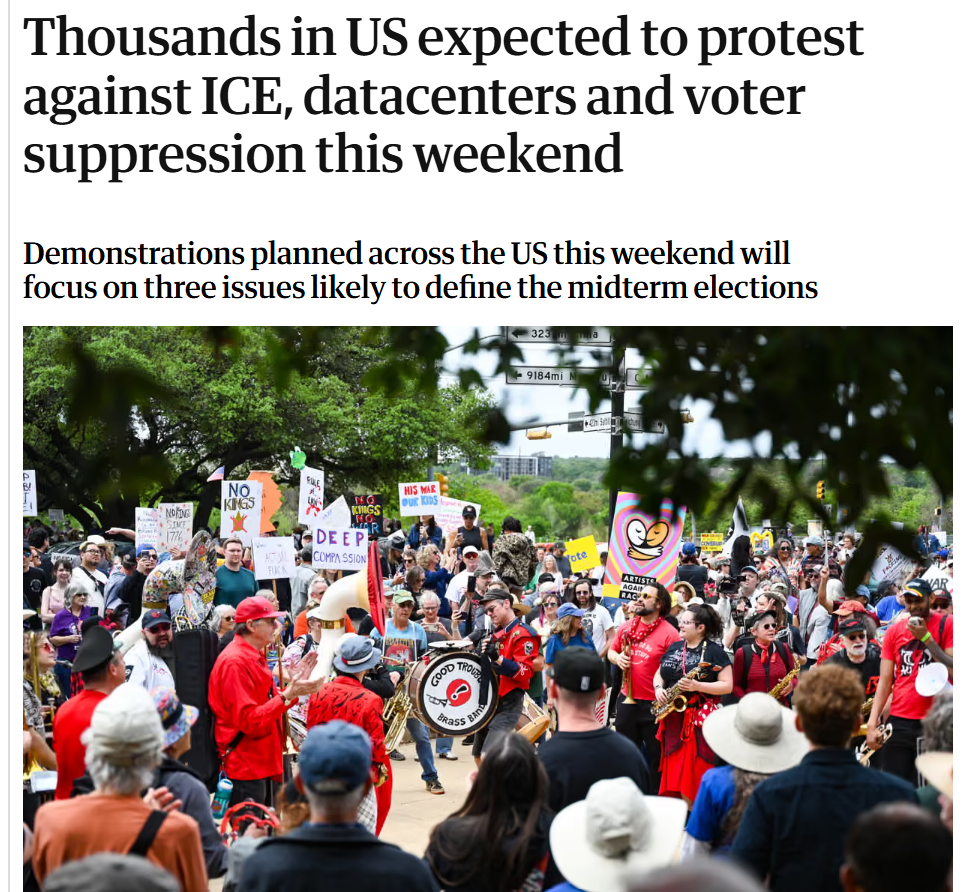
Today in Evanston, Illinois: “Say No to AI Data Centers”.

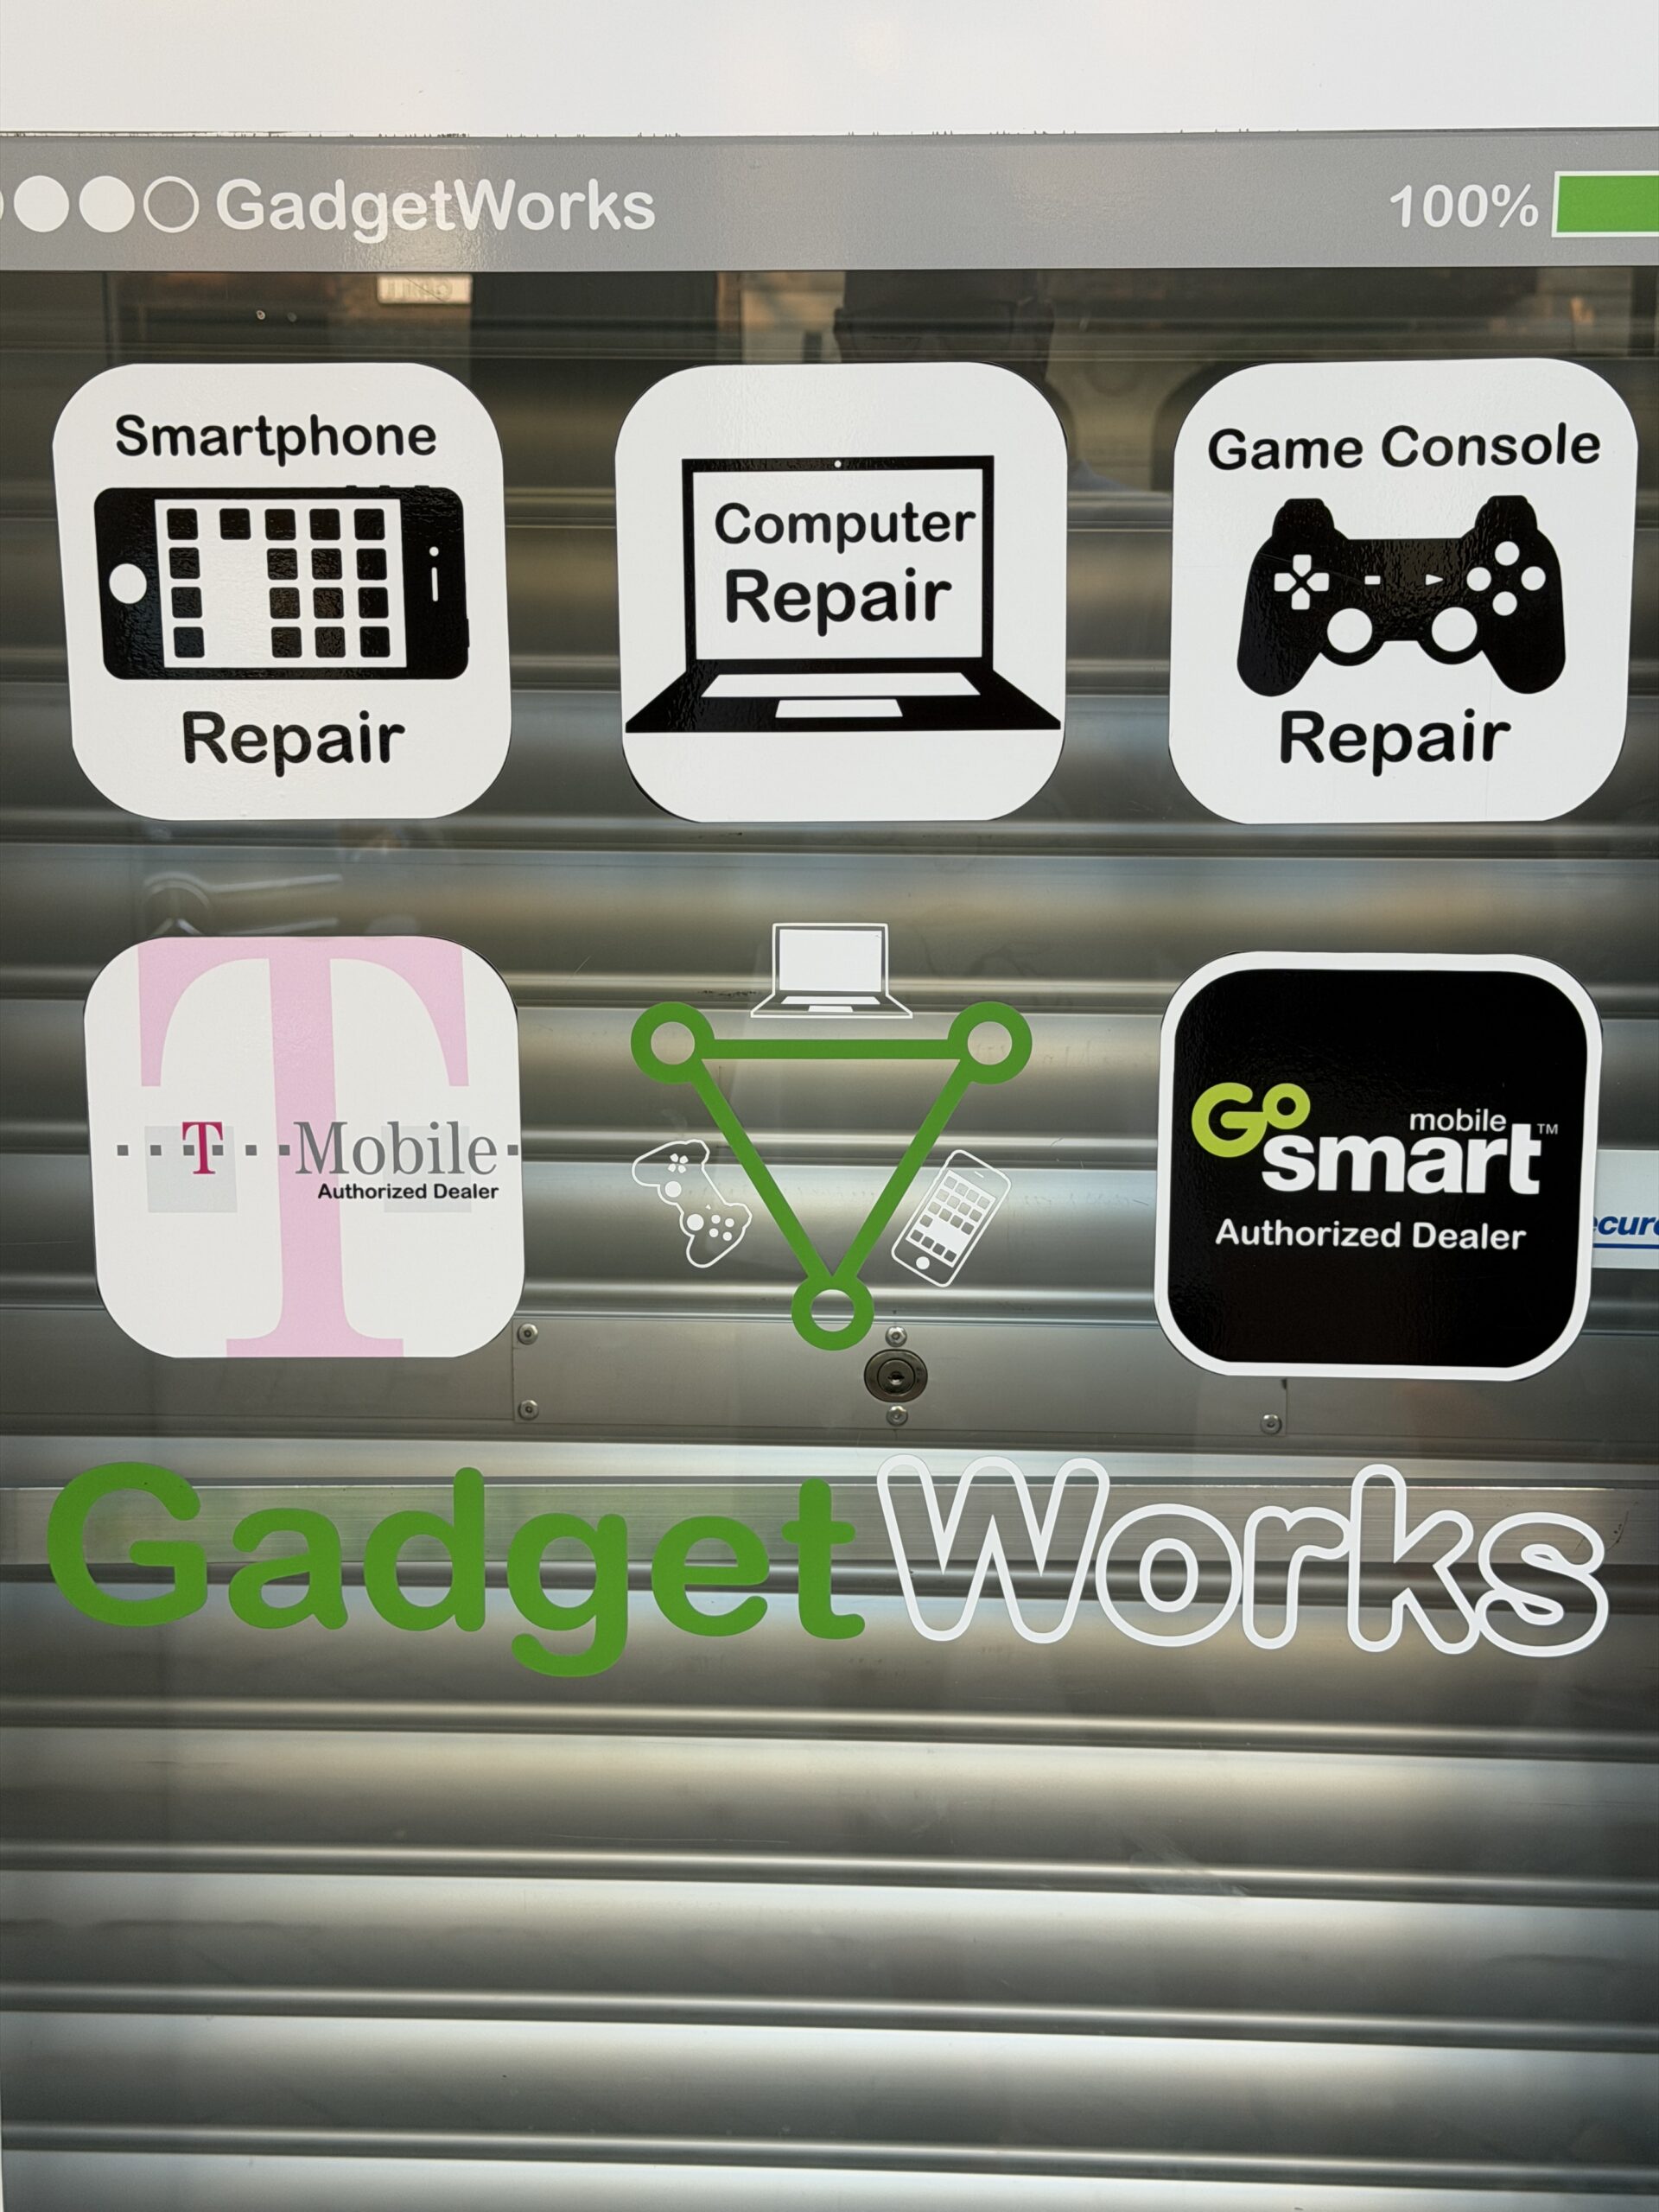
A lot of retailers display this sign, but my favorite is GadgetWorks, whose smartphone and game console customers are in no way dependent on data centers:

The Guardian says that the dream would be to find a data center that is used by ICE and involved in demanding IDs from voters:

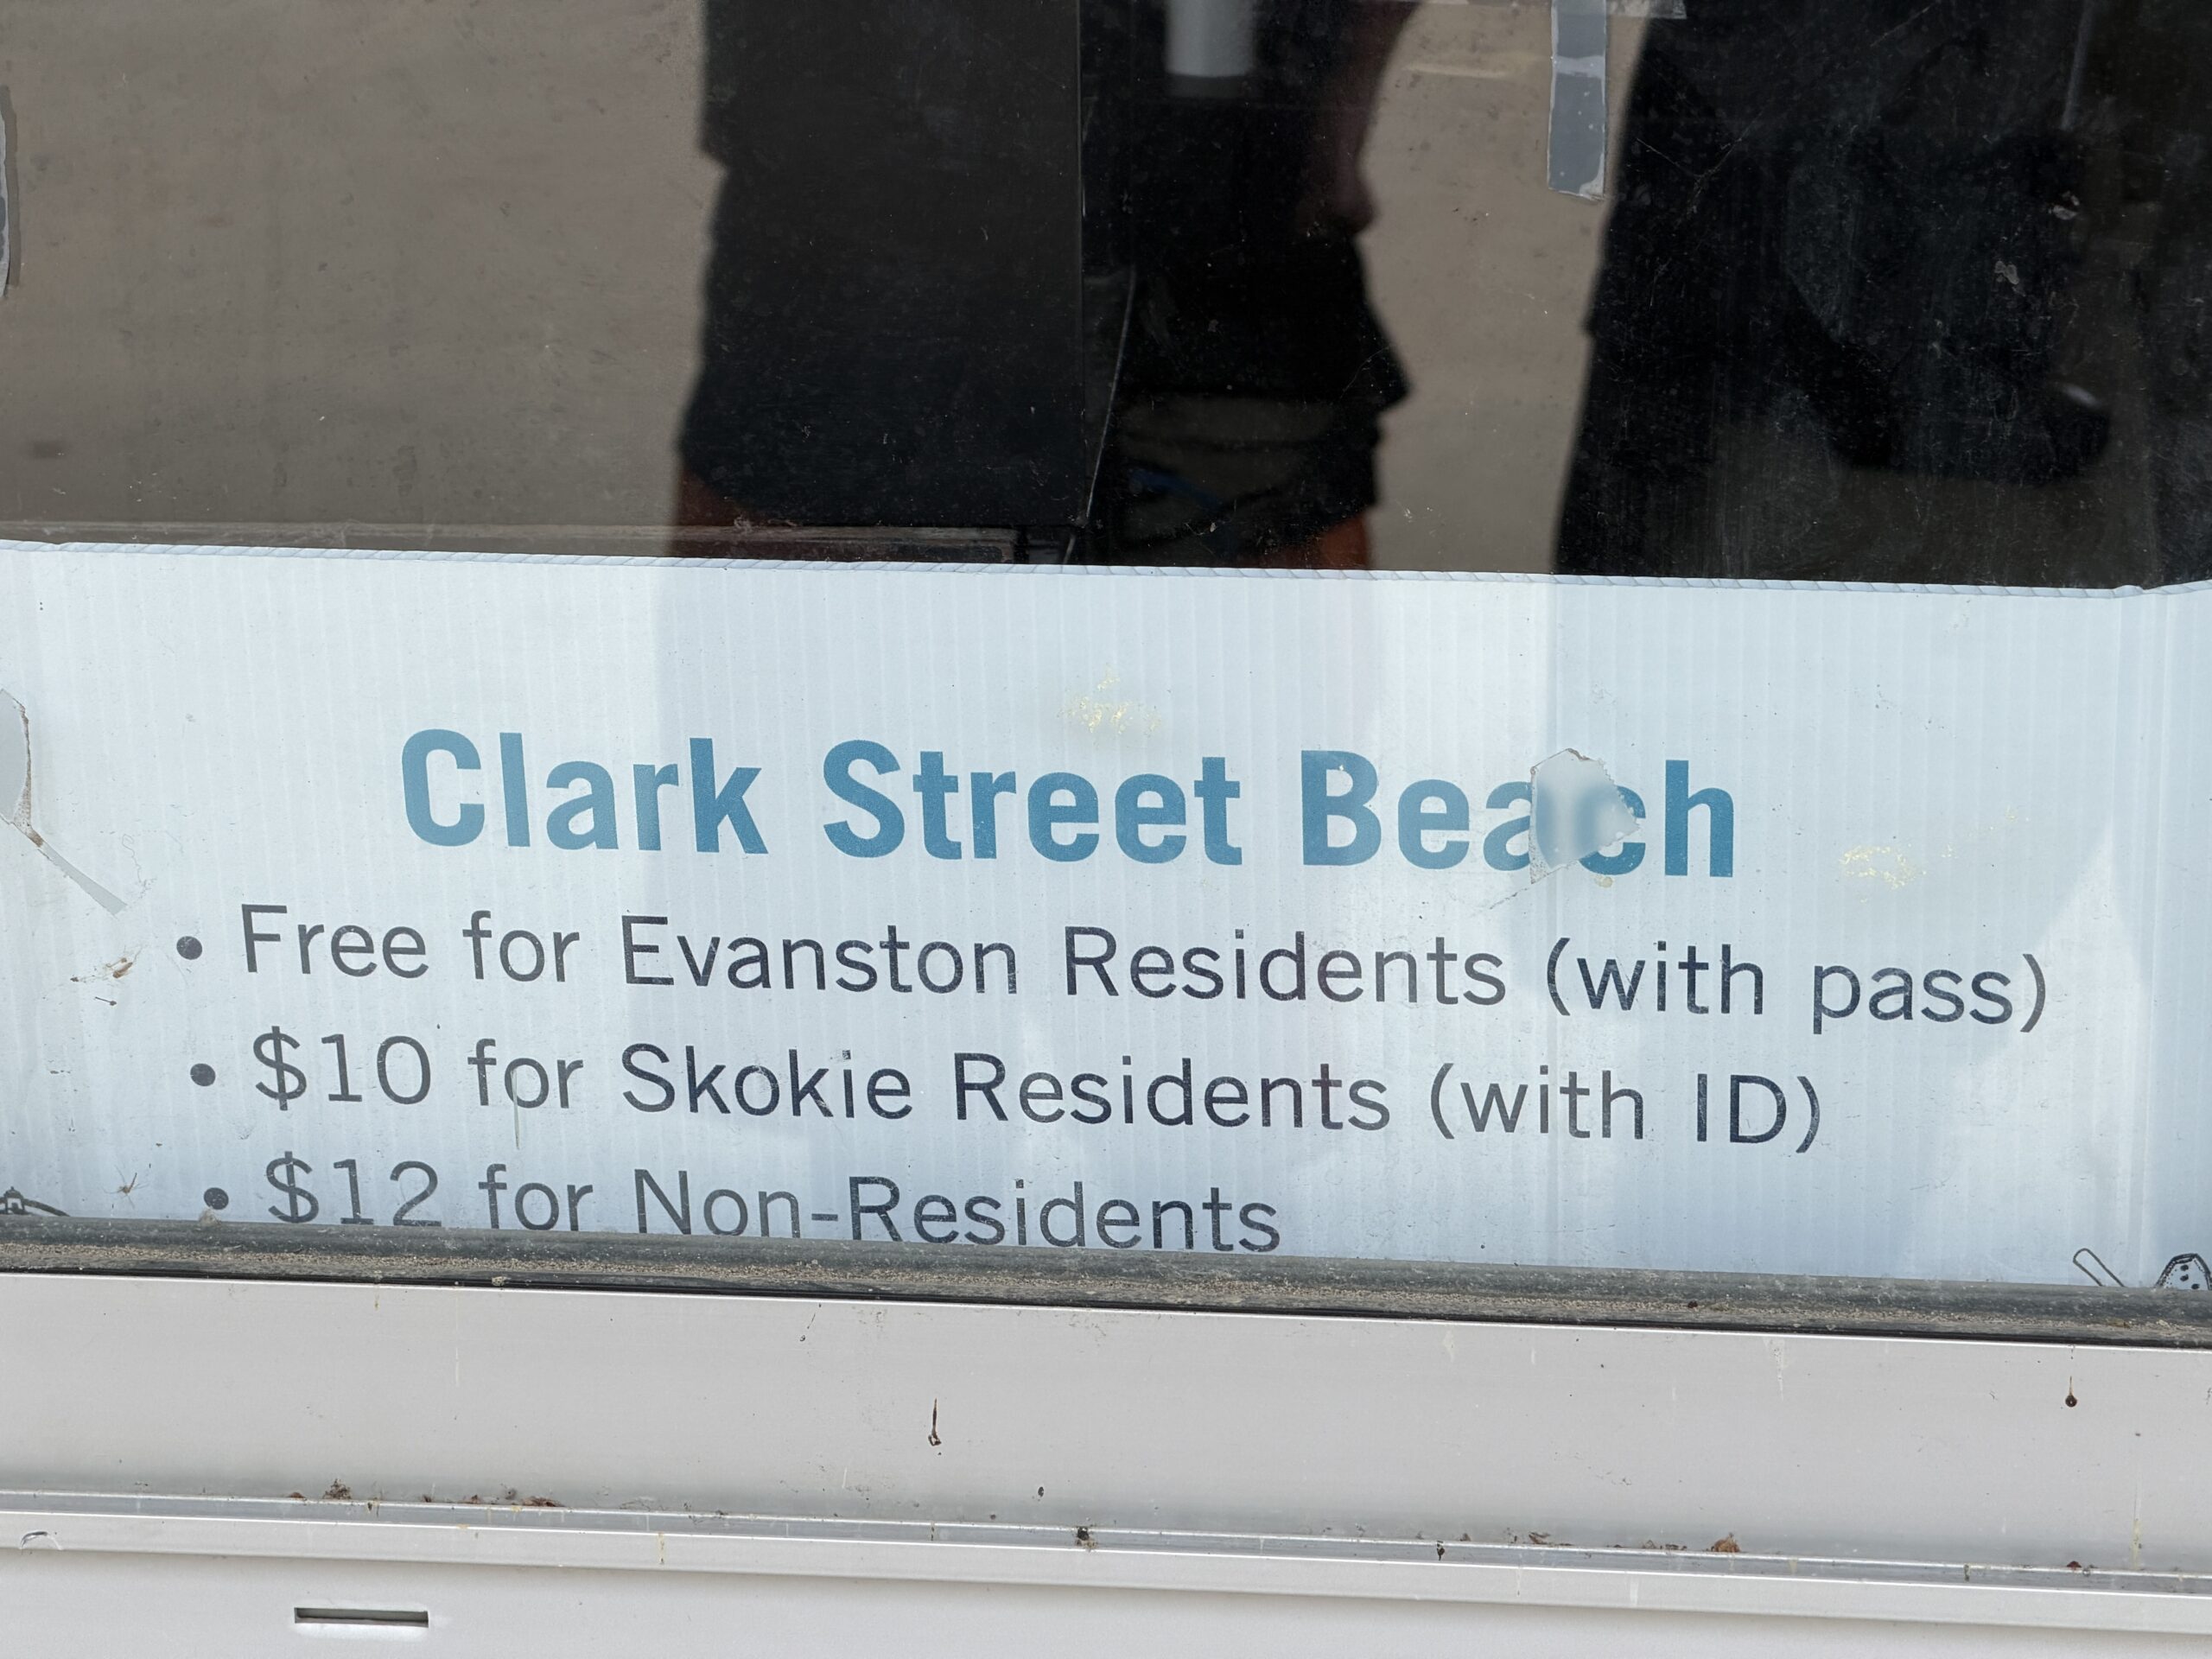
Speaking of ID, although everyone in Evanston seems to agree that requiring ID to vote is unreasonable, the city requires ID of those who wish to visit the local (Lake Michigan) beach:

Full post, including comments
Claude is “marginally the best, but quite expensive”

From a friend who uses LLMs to write code…

Current state of affairs according to me:

OpenAI is at the frontier. There is no reason to use Terra, as there is a Luna or Sol model at an effort level that matches it for cheaper. You can get quite a lot of inference out of the $20/mo plan. $100/mo gives you 5x, but $200/mo gives you 20x, not 10.
Claude Fable is marginally the best, but quite expensive and falls back to Opus on anything it considers remotely questionable, while still charging Fable prices.

Gemini’s latest is 3.5-flash and is well off the curve. The latest non-flash is still 3.1-pro.

GLM 5.2 is the best open weight Chinese model, but its price per token is misleading as it eats up reasoning tokens like crazy.

Best local coding model is probably Qwen 3.6 27B. Gemma 4 is a good local all around model to talk to, but not as good at coding.


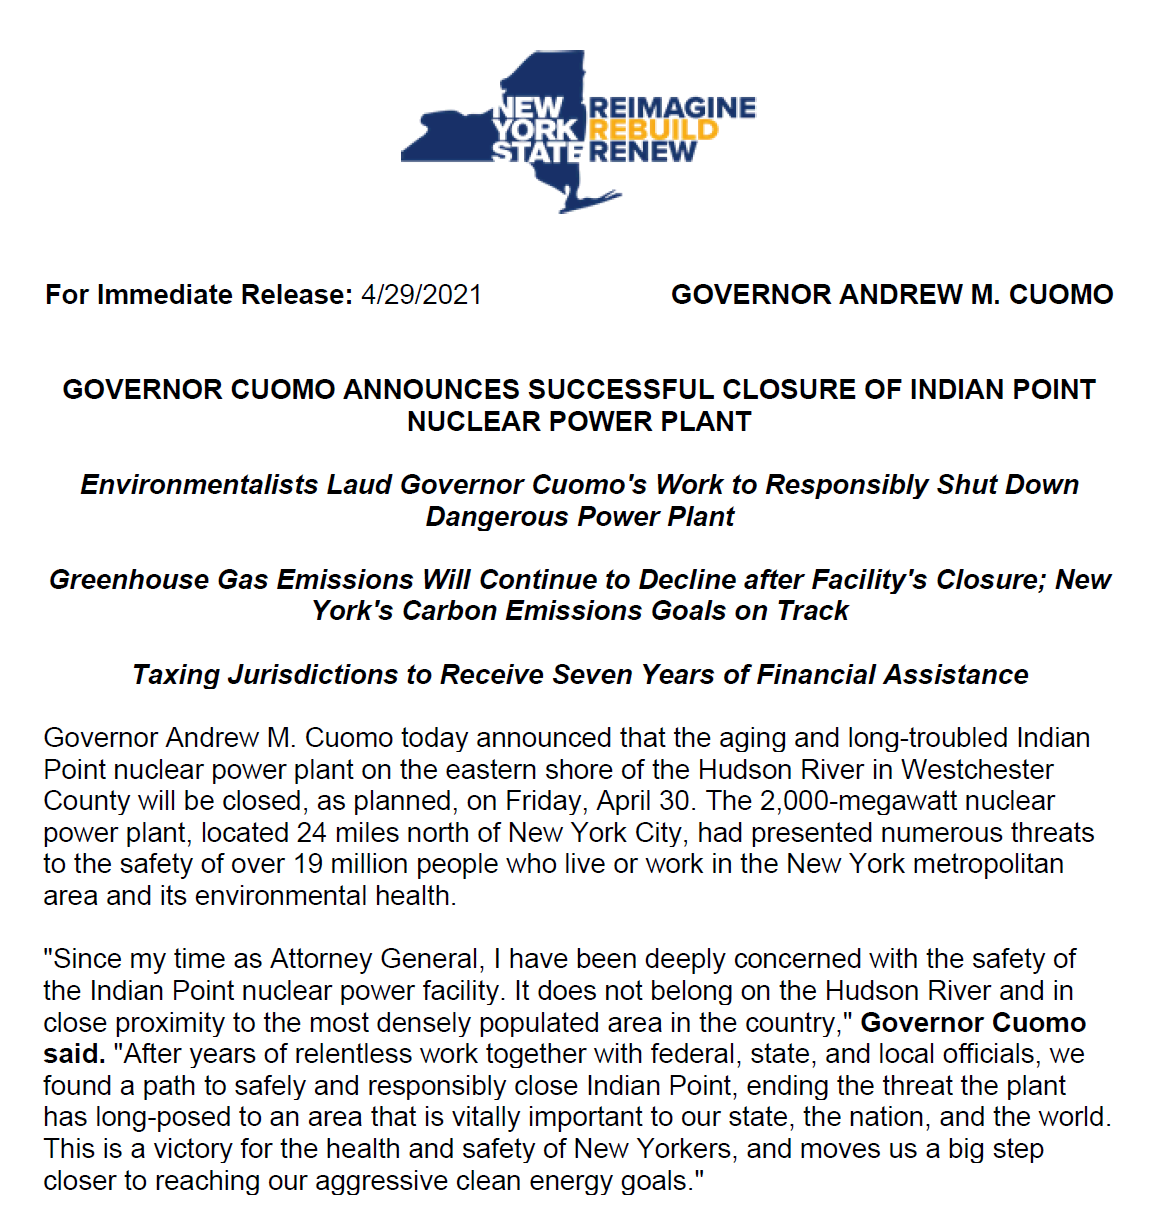
Where will these various models run? New York State has banned data centers, which is forward-thinking but I prefer to reflect on the exquisite timing of the New York political elite in shutting down their massive nuclear electricity plant just one year before the AI/data center boom began (launch of ChatGPT in 2022):

How about AI data centers in space?

Loosely related:

Full post, including comments
Codex works to verify a chart showing Iran having a relatively high level of religious tolerance compared to neighbors

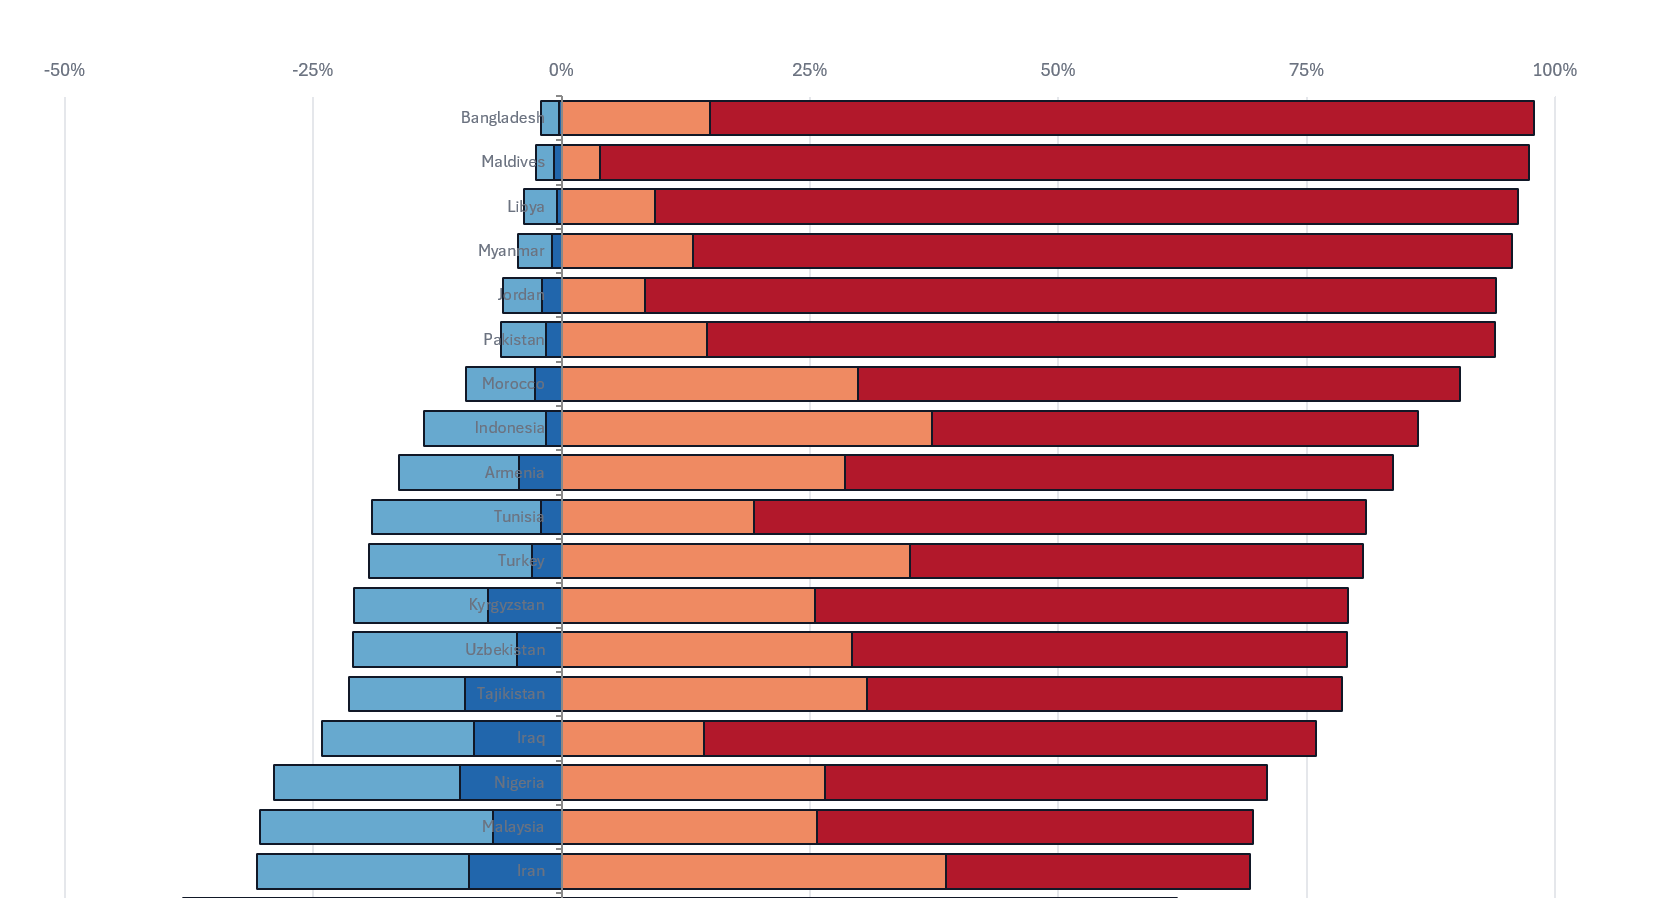
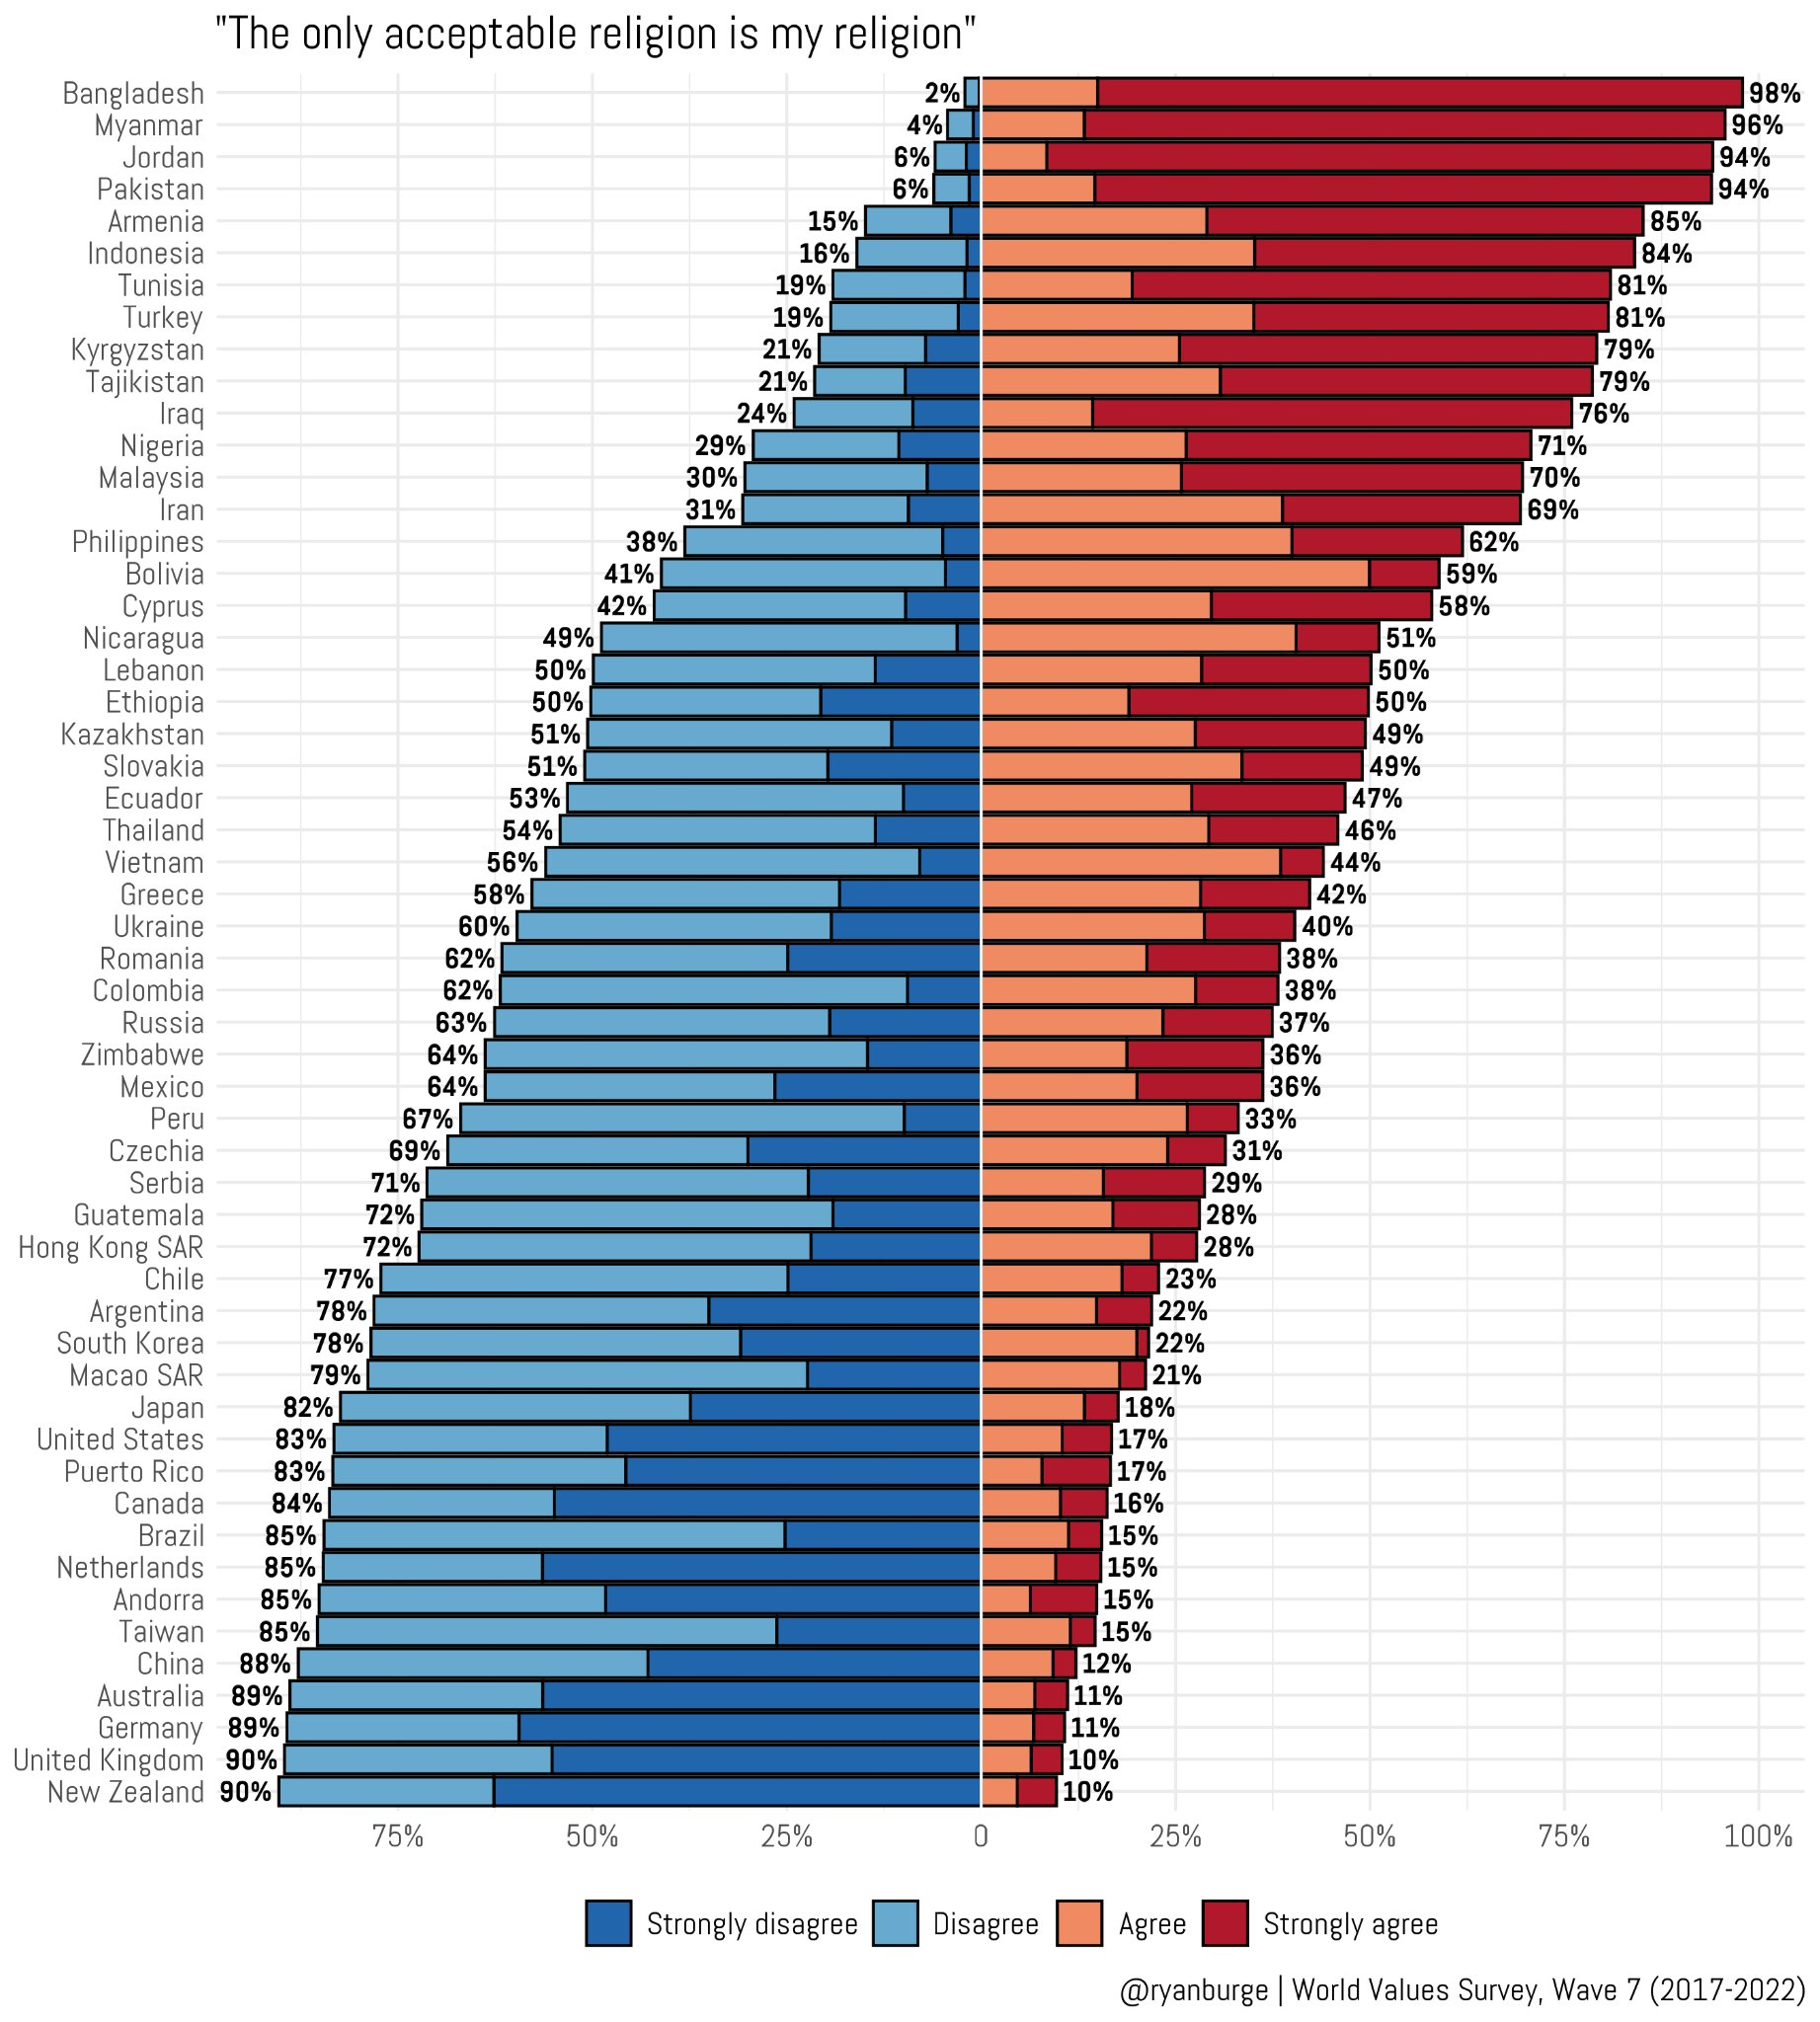
Here’s a chart from an X post charting answers to the question “The only acceptable religion is my religion” (perfect for Pride Month!):

Iranians living in the Islamic Republic of Iran are, according to this chart, much more likely to tolerate non-Islamic belief than, for example, the noble Palestinians who reside in Jordan (whose territory is about 80% of British “Palestine” and in which over 97% of residents are Muslim (0% are Jewish, which makes puts it on track to be celebrated as an ideal society from a progressive point of view)).

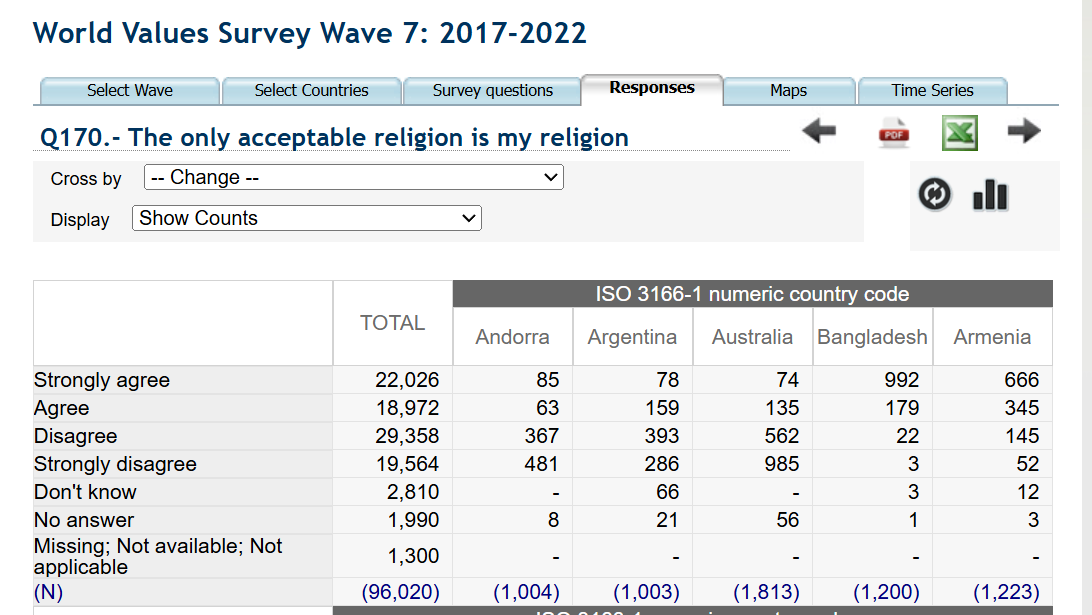
Should we believe this chart? Is it a reasonable size survey, for one thing? I found the cited source and was able to get the raw numbers. 1200 people were surveyed in Bangladesh and only 25 disagreed, consistent with the published bar chart’s percentage.

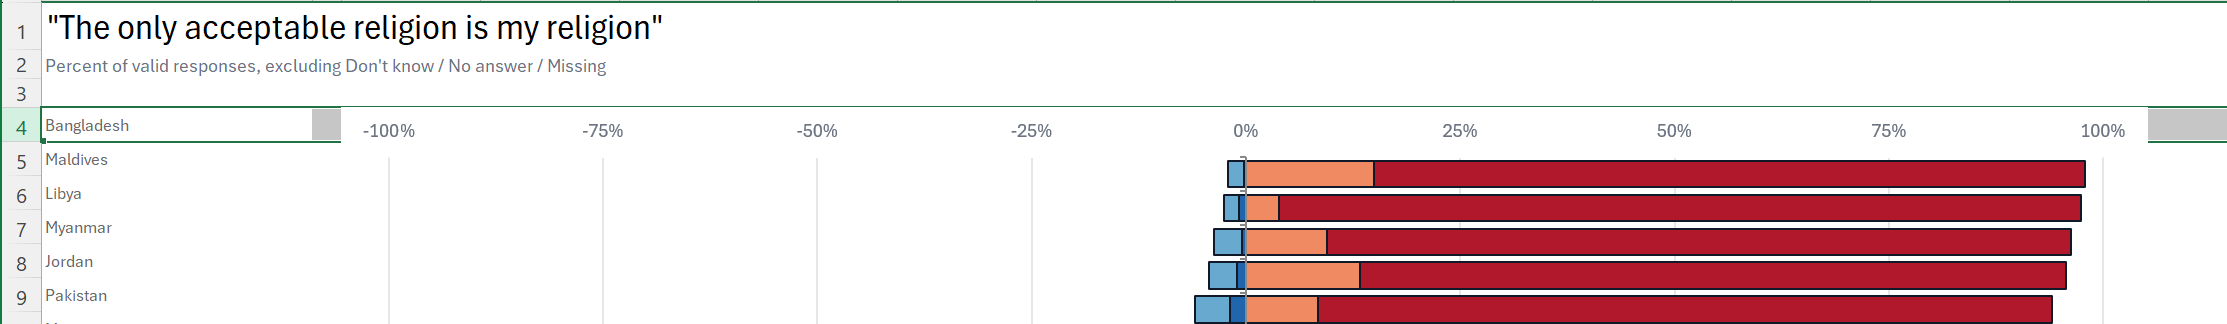
Codex crunched away for about 15 minutes, asking for permission quite a few times (I haven’t ever used it for something like this so maybe the next one will go smoothly). Codex (ChatGPT/OpenAI) concludes that the X chart is a fair representation of the data (i.e., it accomplished a fact check). The Codex-produced chart in Excel is hard to read, though, with the country names buried inside bars of color (not to say “colored bars”):

Note that some countries the X author left out are near the top here, e.g., Maldives (“100% Muslim” according to Google) and Libya (nearly 100% Muslim, according to Google, with the exception of some expats (oil industry workers?)).

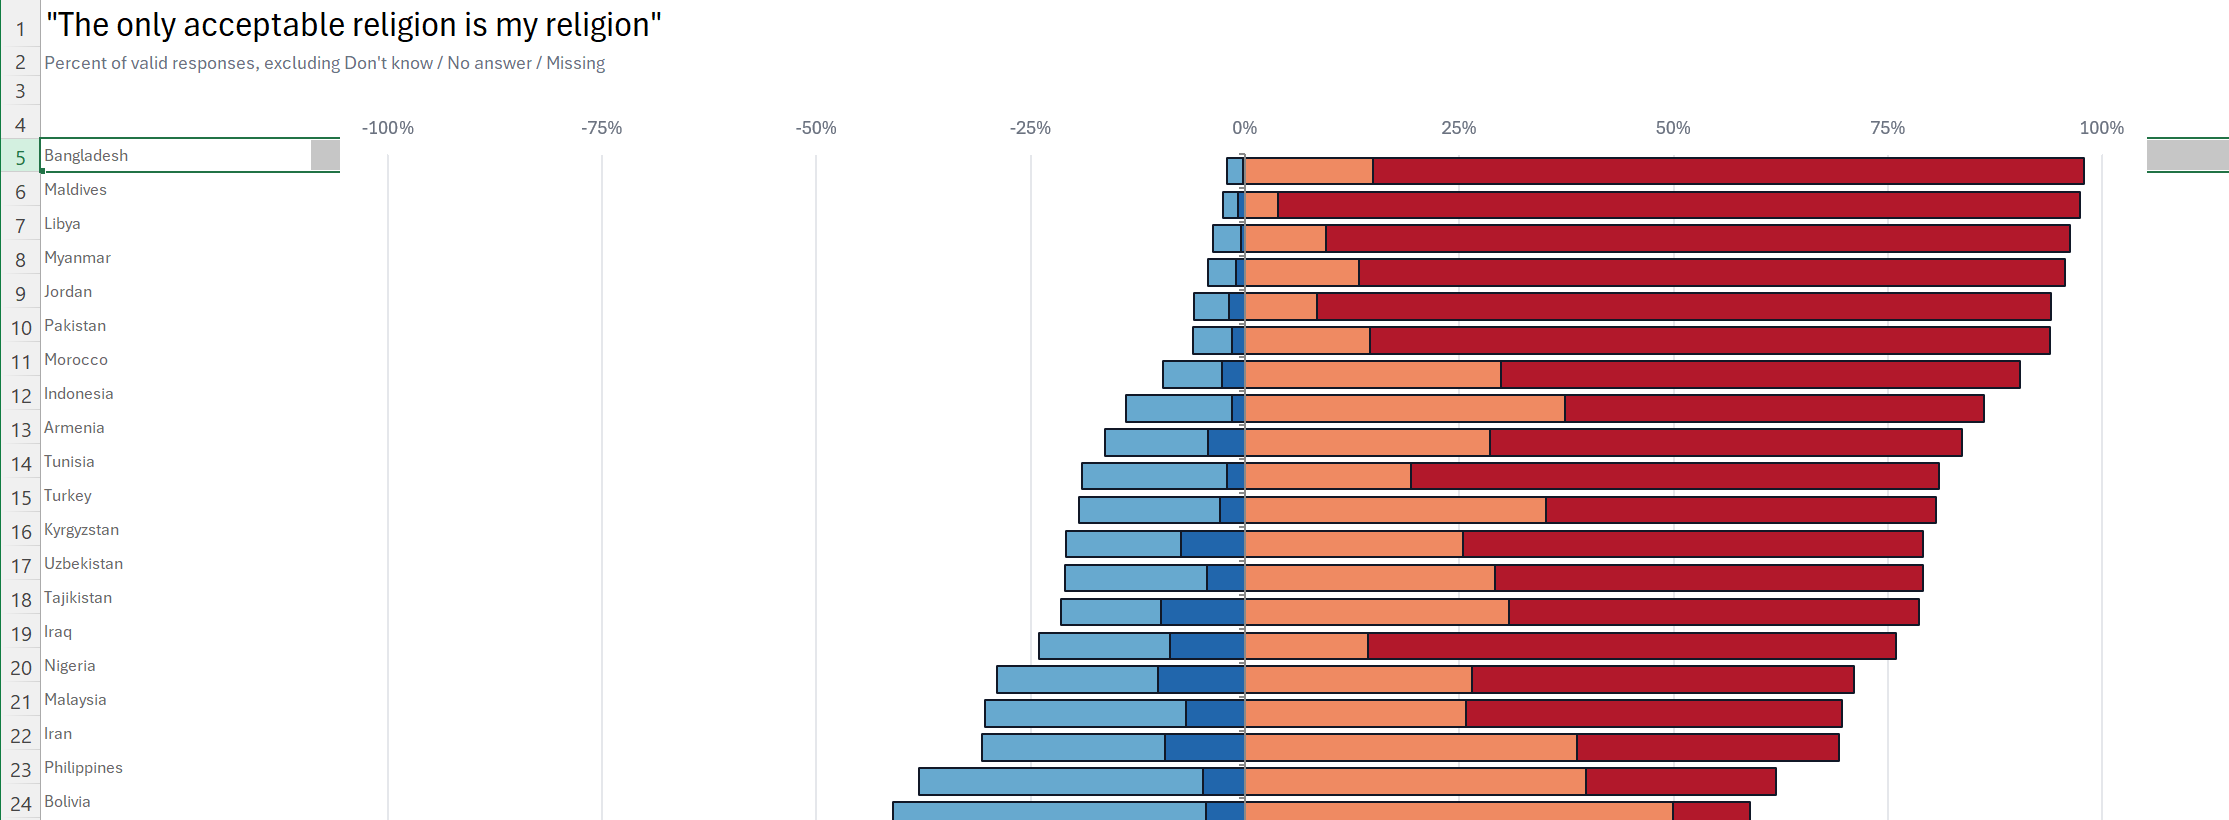
I asked “Can you redo the chart so that the country names are in a separate column? Or at least left-justified?” This took another 10 minutes with many failed attempts and several requests for approval. The result was at least off by one, with the Bangladesh label applied to the percentage legend:

Another 5 minutes and much straining by NVIDIA chips in a data center somewhere…

So the AI assistant does work, but I think that asking a Chatbot to produce a chart, without reference to a desktop computer and Excel, might have been faster/simpler.

Separately, why did we attack a country that is far more tolerant than our NATO ally Turkey (recipient of about $31 billion in aid, cumulatively) and far more tolerant than Jordan, a country to which we have provided $34 billion in aid?

(Loosely related, maybe our surrender to Iran isn’t quite as great a deal for them as portrayed in the media. If it were, wouldn’t the Iranians have already agreed to our surrender? Instead, there are merely negotiations.)

Here’s Codex’s Excel output:

Full post, including comments